↳
In-reply-to
»
All sorts of .de domains don't resolve right now. But not all, movq.de for example still works. All on our server and basically all major other sites are cactus. Maybe some DENIC problem? I'm too tired to investigate, but I'm looking forward to tomorrow to read some report on that. :-) Good night.
⤋ Read More
@movq@www.uninformativ.de Right, they messed up the signing key rotation: https://blog.denic.de/technische-storung-bei-de-domains-behoben/
↳
In-reply-to
»
All sorts of .de domains don't resolve right now. But not all, movq.de for example still works. All on our server and basically all major other sites are cactus. Maybe some DENIC problem? I'm too tired to investigate, but I'm looking forward to tomorrow to read some report on that. :-) Good night.
⤋ Read More
@lyse@lyse.isobeef.org Yep, this was a big oopsie at DENIC:
↳
In-reply-to
»
Just missed the 15th anniversary of the Linux installation on my laptop:
⤋ Read More
@lyse@lyse.isobeef.org Turns out, this actually was a little machine once (small netbook): https://movq.de/blog/postings/2011-04-28/0/POSTING-de.html And then I moved the whole installation to a different laptop later. I love that you can easily do that on Linux.
Some Benefits of Blogging and Writing Online ?~L~X https://thenewleafjournal.com/b/E0f
↳
In-reply-to
»
@prologic Back to slaving away, now that your batteries are fully recharged. But we might be in for some little picturesque treats of QLD and NSW. :-)
⤋ Read More
@bender@twtxt.net Nah, i’m gonna start a blog for our adventure i think instead 😅
Long time no seen! I am updating my pages and blog with a new colour scheme.
The Proper Place For Articles and Blog Posts ?~L~X https://thenewleafjournal.com/b/Dxj
Last year, I made a huge mistake. I repeated on here, what multiple sourcea at Google told me, and what is to this day, written on their blog about Android.
I failed to take into consideration, that people who work at Google, often just lie, or present things intentionally vaguely, so they do not have to follow through with their promises.
I would like to apologize to everyone, who took my previous posts here, as assurance software not explicitly approved by Google, will continue working on Android, past this year (or even just a couple months from now) and that everything has been resolved, as things are now in fact even worse, than they were before. To follow the current state of “Open Android”, please check: https://keepandroidopen.org/
He publicado nueva entrada en mi blog https://yejokjanan.xyz/blog/2026-03-10.html
Added my photo blog with recent updates. Backfilling older stuff… 📷
Synced CSS across my Bear Blog and other site pages. Also using front matter in source markdown files, and outputting meta descriptions ✅
Have put out my first real technical blog post. Also my first use of “info strings” for syntax highlighting 🤓
Just changed my blog’s toast icon, thanks to Robert Birming’s post ♥
My first blog post is live
I’ve created a blog at bearblog.dev, linked above
Blog Questions Challenge Answers ?~L~X https://thenewleafjournal.com/b/DuL
“What is a PC compatible?” https://codon.org.uk/~mjg59/blog/p/what-is-a-pc-compatible/
My little toy operating system from last year runs in 16-bit Real Mode (like DOS). Since I’ve recently figured out how to switch to 64-bit Long Mode right after BIOS boot, I now have a little program that performs this switch on my toy OS. It will load and run any x86-64 program, assuming it’s freestanding, a flat binary, and small enough (< 128 KiB code, only uses the first 2 MiB of memory).
Here I’m running a little C program (compiled using normal GCC, no Watcom trickery):
https://movq.de/v/b27ced6dcb/los86%2D64.mp4
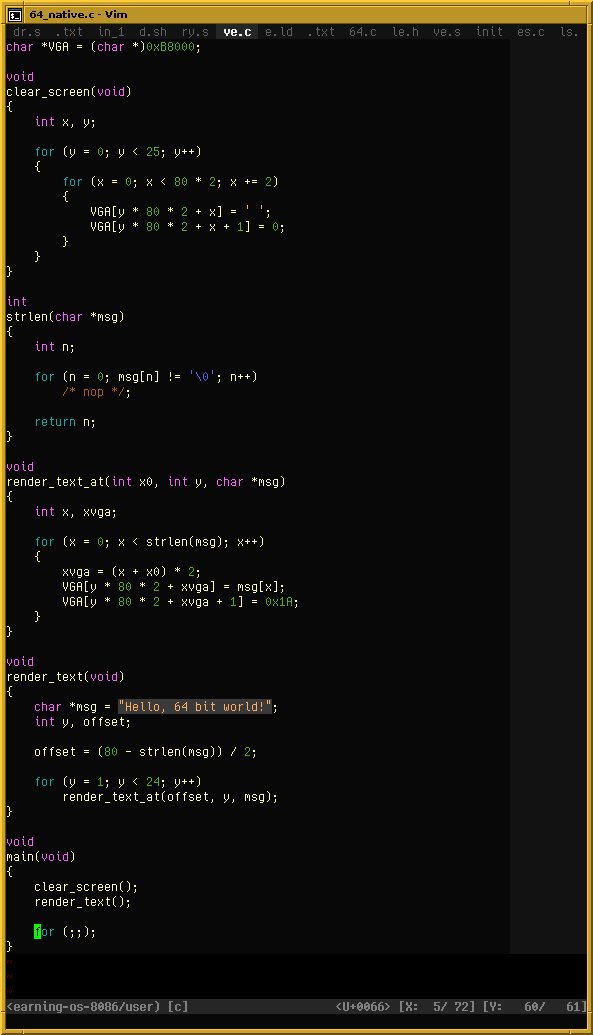
Next steps could include:
- Use Rust instead of C for that 64-bit program?
- Provide interrupt service routines. (At the moment, it just keeps interrupts disabled.)
Happy birthday Katrina! https://www.uninformativ.de/blog/postings/2025-12-23/0/POSTING-en.html :-)
very good blog post that reminded me why it’s taking so long to ship bbycll — previously i had computed the hashes of every post before storing them in the database, after realizing it’s a much better idea to compute the hashes during runtime and only store the post content & timestamp i’m now having to rewrite every function that reads & writes data. i hope the reason as to why i lost motivation is obvious — thankfully i caught it early enough so that once i’m done rewriting just those functions i should™ be able to finalize 1.0-rc with little hassle
↳
In-reply-to
»
Wow, @movq, so many tables. No idea what I expected (I'm totally clueless on this low-level stuff), but that was quite an interesting surprise to me. https://www.uninformativ.de/blog/postings/2025-12-21/0/POSTING-en.html
⤋ Read More
@lyse@lyse.isobeef.org I was surprised by that as well. 😅 I thought these were features that you can use, but no, you must do all this.
By the way, I now fixed the issue that I mentioned at the end and it works on the netbook now. 🥳

Wow, @movq@www.uninformativ.de, so many tables. No idea what I expected (I’m totally clueless on this low-level stuff), but that was quite an interesting surprise to me. https://www.uninformativ.de/blog/postings/2025-12-21/0/POSTING-en.html
↳
In-reply-to
»
H… Ho… How have I not heard about vim-tagbar before? 😳
⤋ Read More
@lyse@lyse.isobeef.org Yeah, well, given that I didn’t need this for such a long time, it’s probably not an essential tool. 😅
I’ve often wanted to have an outline of text documents, though, and tagbar/ctags can do that as well:
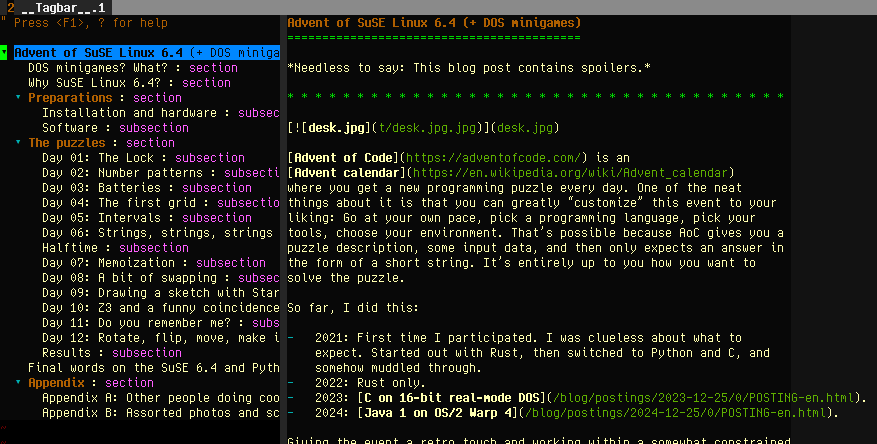
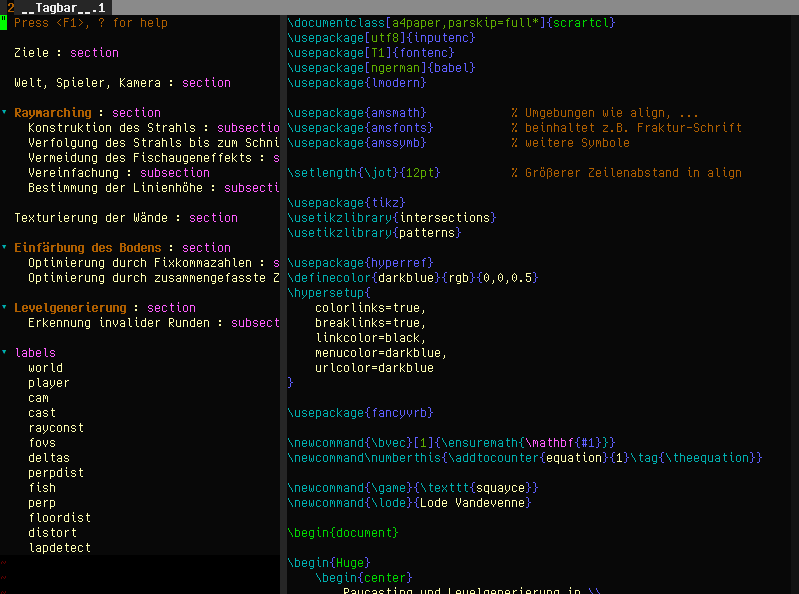
This isn’t as powerful as the “Navigator” tool in StarOffice/LibreOffice (which can be used to rearrange the document), but still pretty useful:
https://www.uninformativ.de/blog/postings/2024-05-23/0/so31.mp4
↳
In-reply-to
»
Advent of Code 2025 starts tomorrow. 🥳🎄
⤋ Read More
Alright, Advent of Code is over:
https://www.uninformativ.de/blog/postings/2025-12-12/0/POSTING-en.html
It’s been quite the time sink, especially with the DOS games on top, but it was fun. 🥳
In case you’re wondering: All puzzles (except for part 2 of day 10) were doable in Python 1 on SuSE Linux 6.4 and ran in a finite time on the Pentium 133. Puzzle 10/2 might have been doable as well if I had better education. 🤣
↳
In-reply-to
»
@aelaraji Ahhh! That would be even funnier and even more brilliant! 🤣 If you can find this, I would happily employ this tactic next time and make 'em pay 💰 Bahahahaha 🤣
⤋ Read More
@prologic@twtxt.net I couldn’t find the exact blog post from before, one that used redirection directives in its nginx config. but I found [this one ](https://melkat.blog/p/unsafe-pricing#:~:text=Something%20else%20I’ve%20been%20doing%20this%20year,%20fine.) mentioning a similar process but done differently.
↳
In-reply-to
»
Tired to re-enable the Ege route to
⤋ Read More
git.mills.io today (after finishing work) and this is what I found 🤯 Tehse asshole/cunts are still at it !!! 🤬 -- So let's instead see if this works:
@prologic@twtxt.net I remember reading a blog-post where someone has been throwing redirects to some +100GB files (usually used for speed testing purposes) at a swarm of bots that has been abusing his server in order to criple them, but I can’t find it anymore. I’m pretty sure I’ve had it bookmarked somewhere.
↳
In-reply-to
»
Up Next:
⤋ Read More
@prologic@twtxt.net if done right, zs derivatives can even generate twtxt feeds alongside RSS for blogs as well
↳
In-reply-to
»
Hmmm 🧐 I'm annectodaly not convinced so-called "AI"(s) really save time™. -- I have no proof though, I would need to do some concrete studies / numbers... -- But, there is one benefit... It can save you from typing and from worsening RSI / Carpal Tunnel.
⤋ Read More
@prologic@twtxt.net AI is slot machines for coders:
- “Before starting tasks, developers forecast that allowing AI will reduce completion time by 24%. After completing the study, developers estimate that allowing AI reduced completion time by 20%. Surprisingly, we find that allowing AI actually increases completion time by 19%–AI tooling slowed developers down.” https://metr.org/blog/2025-07-10-early-2025-ai-experienced-os-dev-study/
- “Stack Overflow data reveals the hidden productivity tax of ‘almost right’ AI code”: https://venturebeat.com/ai/stack-overflow-data-reveals-the-hidden-productivity-tax-of-almost-right-ai-code
The same intermittent reward operant conditioning that gets people addicted to gambling and thinking that if they follow certain rituals they’ll win “next time” drives people’s beliefs that AI tools are making them more productive when they’re making them less productive. I’m going to guess that a side effect of this is that people think they’re typing less when in the longer term they’re typing the same amount or more when you factor in the productivity loss (as far as I’ve read the studies don’t measure this so I’m only guessing).
People are also being rapidly de-skilled by this technology: the more they use it, the more their actual skills atrophy. “Continuous exposure to AI might reduce the ADR (adesoma detection rate) of standard non-AI assisted colonoscopy, suggesting a negative effect on endoscopist behaviour.” (science speak for saying that radiologists get worse at seeing tumors in scans once they’ve used AI): https://www.thelancet.com/journals/langas/article/PIIS2468-1253(25)00133-5/abstract
Nobody who cares about the future should be using this stuff for anything.
https: //cleberg.net/blog/alpine-ssh-hardening.html alpine ssh hardening
Inauguro mi tildelog: https://texto-plano.xyz/~peron/blog/
Thank you for https://www.uninformativ.de/blog/postings/2025-11-09/0/POSTING-en.html, @movq@www.uninformativ.de! I never configured systemd timers, but I would have gotten it wrong, too. Good to know when I eventually stumble across that in the future. I’m still using cron. Yeah, its field order sucks and I always have to look it up (because I don’t deal with that all that often). Indeed, systemd’s order sounds more reasonable.
↳
In-reply-to
»
Double congrats, @thecanine! \o/
⤋ Read More
@lyse@lyse.isobeef.org It’s possible to run the validator locally (my blog generator scripts do that):
https://validator.w3.org/nu/about.html
That way you don’t forget. 🥳
↳
In-reply-to
»
@bender Thanks for this illustration, it completely “misunderstood” everything I wrote and confidently spat out garbage. 👌
⤋ Read More
@prologic@twtxt.net Let’s go through it one by one. Here’s a wall of text that took me over 1.5 hours to write.
The criticism of AI as untrustworthy is a problem of misapplication, not capability.This section says AI should not be treated as an authority. This is actually just what I said, except the AI phrased/framed it like it was a counter-argument.
The AI also said that users must develop “AI literacy”, again phrasing/framing it like a counter-argument. Well, that is also just what I said. I said you should treat AI output like a random blog and you should verify the sources, yadda yadda. That is “AI literacy”, isn’t it?
My text went one step further, though: I said that when you take this requirement of “AI literacy” into account, you basically end up with a fancy search engine, with extra overhead that costs time. The AI missed/ignored this in its reply.
Okay, so, the AI also said that you should use AI tools just for drafting and brainstorming. Granted, a very rough draft of something will probably be doable. But then you have to diligently verify every little detail of this draft – okay, fine, a draft is a draft, it’s fine if it contains errors. The thing is, though, that you really must do this verification. And I claim that many people will not do it, because AI outputs look sooooo convincing, they don’t feel like a draft that needs editing.
Can you, as an expert, still use an AI draft as a basis/foundation? Yeah, probably. But here’s the kicker: You did not create that draft. You were not involved in the “thought process” behind it. When you, a human being, make a draft, you often think something like: “Okay, I want to draw a picture of a landscape and there’s going to be a little house, but for now, I’ll just put in a rough sketch of the house and add the details later.” You are aware of what you left out. When the AI did the draft, you are not aware of what’s missing – even more so when every AI output already looks like a final product. For me, personally, this makes it much harder and slower to verify such a draft, and I mentioned this in my text.
Skill Erosion vs. Skill EvolutionYou, @prologic@twtxt.net, also mentioned this in your car tyre example.
In my text, I gave two analogies: The gym analogy and the Google Translate analogy. Your car tyre example falls in the same category, but Gemini’s calculator example is different (and, again, gaslight-y, see below).
What I meant in my text: A person wants to be a programmer. To me, a programmer is a person who writes code, understands code, maintains code, writes documentation, and so on. In your example, a person who changes a car tyre would be a mechanic. Now, if you use AI to write the code and documentation for you, are you still a programmer? If you have no understanding of said code, are you a programmer? A person who does not know how to change a car tyre, is that still a mechanic?
No, you’re something else. You should not be hired as a programmer or a mechanic.
Yes, that is “skill evolution” – which is pretty much my point! But the AI framed it like a counter-argument. It didn’t understand my text.
(But what if that’s our future? What if all programming will look like that in some years? I claim: It’s not possible. If you don’t know how to program, then you don’t know how to read/understand code written by an AI. You are something else, but you’re not a programmer. It might be valid to be something else – but that wasn’t my point, my point was that you’re not a bloody programmer.)
Gemini’s calculator example is garbage, I think. Crunching numbers and doing mathematics (i.e., “complex problem-solving”) are two different things. Just because you now have a calculator, doesn’t mean it’ll free you up to do mathematical proofs or whatever.
What would have worked is this: Let’s say you’re an accountant and you sum up spendings. Without a calculator, this takes a lot of time and is error prone. But when you have one, you can work faster. But once again, there’s a little gaslight-y detail: A calculator is correct. Yes, it could have “bugs” (hello Intel FDIV), but its design actually properly calculates numbers. AI, on the other hand, does not understand a thing (our current AI, that is), it’s just a statistical model. So, this modified example (“accountant with a calculator”) would actually have to be phrased like this: Suppose there’s an accountant and you give her a magic box that spits out the correct result in, what, I don’t know, 70-90% of the time. The accountant couldn’t rely on this box now, could she? She’d either have to double-check everything or accept possibly wrong results. And that is how I feel like when I work with AI tools.
Gemini has no idea that its calculator example doesn’t make sense. It just spits out some generic “argument” that it picked up on some website.
3. The Technical and Legal Perspective (Scraping and Copyright)The AI makes two points here. The first one, I might actually agree with (“bad bot behavior is not the fault of AI itself”).
The second point is, once again, gaslighting, because it is phrased/framed like a counter-argument. It implies that I said something which I didn’t. Like the AI, I said that you would have to adjust the copyright law! At the same time, the AI answer didn’t even question whether it’s okay to break the current law or not. It just said “lol yeah, change the laws”. (I wonder in what way the laws would have to be changed in the AI’s “opinion”, because some of these changes could kill some business opportunities – or the laws would have to have special AI clauses that only benefit the AI techbros. But I digress, that wasn’t part of Gemini’s answer.)
tl;drExcept for one point, I don’t accept any of Gemini’s “criticism”. It didn’t pick up on lots of details, ignored arguments, and I can just instinctively tell that this thing does not understand anything it wrote (which is correct, it’s just a statistical model).
And it framed everything like a counter-argument, while actually repeating what I said. That’s gaslighting: When Alice says “the sky is blue” and Bob replies with “why do you say the sky is purple?!”
But it sure looks convincing, doesn’t it?
Never againThis took so much of my time. I won’t do this again. 😂
↳
In-reply-to
»
Hello again everyone! A little update on my twtxt client.
⤋ Read More
@zvava@twtxt.net @bender@twtxt.net At first I added it without thinking when planning the possible fields based on other UIs I was researching.
I was about to discard it but after thinking about it a bit I noticed that the services allowing to have a separated nick and display_name could unlock some good uses.
For example some added context or at-a-glance information like pronouns or statuses (like Artist [Accepting commissions] or App Name (v2.5)) while other used a more readable version of the nick (blog.domain.com became Person Name's Blog).
Of course it is absolutely optional and it can be safely ignored, but with my vision of being able to build more that a pure twtxt clients, giving it a first-class support just like the other known fields felt right to me.
And my new migrated blog is up woohoo 🥳 https://prologic.blog/
I think I’m just about ready to go live with my new blog (migrated from MicroPub). I just finished migrating all of the content over, fixing up metadata, cleaning up, migrating media, optimizing media.
The new blog for prologic.blog soon to be powered by zs using the zs-blog-template is coming along very nicely 👌 It was actually pretty easy to do the migration/conversation in the end. The results are not to shabby either.
Before:
- ~50MB repo
- ~267 files
After:
- ~20MB repo
- ~88 files
↳
In-reply-to
»
Pretty happy with my zs-blog-template starter kit for creating and maintaining your own blog using zs 👌 Demo of what the starter kit looks like here -- Basic features include:
⤋ Read More
@bender@twtxt.net I’ve made several improvements today, tightened up the line height and density of the text plus a few other nice things too! I think I’m ready to start migrating my blog over to this 😅
Pretty happy with my zs-blog-template starter kit for creating and maintaining your own blog using zs 👌 Demo of what the starter kit looks like here – Basic features include:
- Clean layout & typography
- Chroma code highlighting (aligned to your site palette)
- Accessible copy-code button
- “On this page” collapsible TOC
- RSS, sitemap, robots
- Archives, tags, tag cloud
- Draft support (hidden from lists/feeds)
- Open Graph (OG) & Twitter card meta (default image + per-post overrides)
- Ready-to-use 404 page
As well as custom routes (redirects, rewrites, etc) to support canonical URLs or redirecting old URLs as well as new zs external command capability itself that now lets you do things like:
$ zs newpost
to help kick-start the creation of a new post with all the right “stuff”™ ready to go and then pop open your $EEDITOR 🤞
Phlog is a blog for gopher. Web Log - Blog, Gopher log - Phlog.
↳
In-reply-to
»
https://zsblog.mills.io/ for anyone interested. I think I still have some small tweaking to do befor eI use this for realz.
⤋ Read More
@prologic@twtxt.net I can’t upload a screenshot (tried, but Yarnd simple “ate” my reply). See https://zsblog.mills.io/posts/hello-zs-blog.html. Is has no date/time on it.
↳
In-reply-to
»
I just created a zs blogging template which I'm going to use for https://prologic.blog and I might starting writing long-form again soon™ 🔜 So far the "blogging" template/engine (if you weill) is quite simple. It comprises essentially of an
⤋ Read More
index.md a prehook and a few utilities:
@bender@twtxt.net Yes I did about a week or so ago. It took me a lot of effort to get the content even rendered in the first place. LOL I had to basically export my blog as HTML (can you believe that?!) – The Hugo export just didn’t work at all 🤣
I just created a zs blogging template which I’m going to use for https://prologic.blog and I might starting writing long-form again soon™ 🔜 So far the “blogging” template/engine (if you weill) is quite simple. It comprises essentially of an index.md a prehook and a few utilities:
$ git ls-files
.gitignore
.zs/config.yml
.zs/editthispage
.zs/include
.zs/layout.html
.zs/list
.zs/months
.zs/now
.zs/onthispage
.zs/posthook
.zs/postsbymonth
.zs/prehook
.zs/scripts
.zs/styles
.zs/tagcloud
.zs/taglist
.zs/years
archives/.empty
assets/css/site.css
assets/js/main.js
index.md
posts/hello-zs-blog.md
posts/on-tagging.md
posts/second-post.md
tags/.empty
Secured Debian Installation https://blog.miu.guru/guides/secure-debian/
added opengraph to my blog :D https://bubblegum.girlonthemoon.xyz/articles/underground-soundcloud-remixes
Thanks to a blog post by ~solderpunk and the presence of ImageMagick on my pubnix, all of my weirdcore art (apart from the animated works) is now under 32K in size! Honestly, I’d say the lower JPEG quality actually adds to the vibe of the images: something from the early web, taken permanently out of context and long forgotten.
Is that really necessary? How hard is it to make a 32-bit build? 🤔 Honest question. https://blog.mozilla.org/futurereleases/2025/09/05/firefox-32-bit-linux-support-to-end-in-2026/
↳
In-reply-to
»
The bots have begun to access my website way more often. I’m getting about 120k hits on https://www.uninformativ.de/git/ now in a couple of hours.
⤋ Read More
As expected: Didn’t last long. They’re coming from different IPs now.
I’ve read enough blog posts by other people to know that this is probably pointless. The bots have so many IPs/networks at their disposal …
This is soooo bloody cool, @movq@www.uninformativ.de! https://www.uninformativ.de/blog/postings/2025-08-30/0/POSTING-en.html