↳
In-reply-to
»
@movq Regarding https://movq.de/blog/postings/2026-06-16/0/POSTING-en.html:
⤋ Read More
@lyse@lyse.isobeef.org In what way was KDE 3’s menu organized? KDE 1 is the only KDE version I ever used. 😅 We’re talking about this one, right?
Isn’t Notepad++ and Python cheating!? :-D
Well, Python was certainly already a thing back then, but Notepad++ is from 2003, right. I think I used https://www.wintotal.de/download/proton/ at the time? Maybe? I don’t know. 😅
The dairy farm has a new milk vending machine. The prices increased by 20%. One liter is now 1.20€ instead of 1.00€. But I don’t complain.
In a few meters of shrubs there were easily 50 butterflies. That was crazy, I’ve never seen this many in one spot. I should have taken a video.
The grain field in the beginning was looking so great. Crazy colorful and very yummy looking. I would have loved to take a bite. Or at least lie down right in the middle.
That was another great time in the outdoors. The 21°C were killing us, though. We were always glad when we reached a shady spot with a little breeze. I’m not gonna survive the 35°C later this week. :-(
↳
In-reply-to
»
Oh boy, I absolutely hate this stupid trend of not writing changelogs anymore! Why the fuck would one seriously consider it to be a viable option to just let some shitty bot spew all merge requests on a goddamn GitHub release?! First of all, these merge request titles suck balls. The order of the changes in this "changelog" is completely random (well, probably merge time, which is as useless as the dick on the Pope). They are not grouped by anything at all. Additions, changes, removals, deprecations, etc. randomly mixed up in one giant list. And then "Add feature X", seventeen kilometers further down "Revert 'Add feature X'". Fuck you! Don't include this shit in the first place!
⤋ Read More
@movq@www.uninformativ.de I just ran across another thing. At least I personally couldn’t care less about CI infrastructure changes. Whether they’re using github action a or b or c or version v or w, it is not of my interest. At all. (It might be useful to estimate the supply chain attack risk, though.) If the maintainers want to include them in the changelog – and there are probably people to whom this information is crucial – it’s probably best to document CI infrastructure changes in their own section.
↳
In-reply-to
»
Every now and then, I think that I have carefully proof-read my message enough times and hit the "Add message" button in
⤋ Read More
tt. But then, in the message tree, I spot another missed typo. My process is then to go to my twtxt.txt and fix it by hand. However, I still have to clean up tt's cache. This is rather tidious:
With multicolored TUIs, I find it usually hard to immediately tell which button is selected if there are just two.
Indeed, I wouldn’t be able to tell in that example, either. movwin works around that by (mostly) assuming that there is no support for colors at all, so there should always be a way to tell which widget has focus, even without colors. That’s why it puts brackets around a button’s label when focused:


The fewer colors you use, the better, I guess. 🤔
↳
In-reply-to
»
Every now and then, I think that I have carefully proof-read my message enough times and hit the "Add message" button in
⤋ Read More
tt. But then, in the message tree, I spot another missed typo. My process is then to go to my twtxt.txt and fix it by hand. However, I still have to clean up tt's cache. This is rather tidious:
Getting the vim key bindings to work for focus switching in this modal dialog took me forever. Only cursors and (Shift+)Tab are supported out of the box. I absolutely understand that, it’s fine. I installed an input handler on the dialog, but the focus always stayed the same.
After two wasted hours, I was in despair to copy the tview.Modal into my own code base. Of course, I had to fix all the private tview field accesses first. But even installing the input handler directly on the buttons themselves did not work. Even though, the handler was definitely executed, the focus did not shift. Forcing redraws as a last resort also did not work.
Looking through all the messy chained input handling, I eventually stumbled across another place in the tview.Form, which is internally used by tview.Modal. This messed around with app focus receptions and input handlers. This gave me the idea to make the tview.Application refocus my modal dialog after I told the modal dialog which button to select. And would you look at that, this did the trick! I haven’t completely figured out what is going on exactly, but I could get rid of my Modal clone again.
I always go through hell with focus handling in tview. Each and every time. It just does not feel natural to me. Complete brainfuck to wrap my head around. The Urwid API felt sooo much more refined, it never was an issue. It just works. In fact, I cannot think of any other TUI library that has remotely the same pain level when it comes to focusing widgets as tview.
Now I’m curious how movwin deals with that. ;-)
Cleaning up my ecosystem today, catching stray services and use cases. After that, some more OpenBSD learning.
↳
In-reply-to
»
Oh boy, I absolutely hate this stupid trend of not writing changelogs anymore! Why the fuck would one seriously consider it to be a viable option to just let some shitty bot spew all merge requests on a goddamn GitHub release?! First of all, these merge request titles suck balls. The order of the changes in this "changelog" is completely random (well, probably merge time, which is as useless as the dick on the Pope). They are not grouped by anything at all. Additions, changes, removals, deprecations, etc. randomly mixed up in one giant list. And then "Add feature X", seventeen kilometers further down "Revert 'Add feature X'". Fuck you! Don't include this shit in the first place!
⤋ Read More
@lyse@lyse.isobeef.org Thanks!
On the AI changelog part, though, I’d rather recommend to just not have a changelog at all.
I’m afraid that ship has sailed. You can rest assured that someone who uses AI/LLMs for their code (which is almost everybody at this point) will most certainly also use it for changelogs.
I actually considered not mentioning AI output at all, because this just opens a huge can of worms … 😞
While going through these terrible GitHub release pages, I also found these “New Project Contributors” sections
Yeah, they play on a nerd’s pride.
Now, it’s just the same auto shitshow with MR titles in a rolling date-versioned release scheme. It’s just our team who has to deal with that, though. I think I’m the only one who is not a fan of it.
I’ve found that this whole situation is much worse at work than it is in the Free Software world. At work, it’s literally work and hardly anybody actually cares. We still don’t have all people convinced that writing good commit messages or using good branch names is worth the time. It’s … oh god, no, I’m going to stop here, this is bad for my mental health. 😅
Suffice it to say, all release notes at work are now AI-generated. Nobody gives a fuck.
↳
In-reply-to
»
Oh boy, I absolutely hate this stupid trend of not writing changelogs anymore! Why the fuck would one seriously consider it to be a viable option to just let some shitty bot spew all merge requests on a goddamn GitHub release?! First of all, these merge request titles suck balls. The order of the changes in this "changelog" is completely random (well, probably merge time, which is as useless as the dick on the Pope). They are not grouped by anything at all. Additions, changes, removals, deprecations, etc. randomly mixed up in one giant list. And then "Add feature X", seventeen kilometers further down "Revert 'Add feature X'". Fuck you! Don't include this shit in the first place!
⤋ Read More
@movq@www.uninformativ.de Hahaha, great timing! :-D I love your article and agree with almost all your points.
On the AI changelog part, though, I’d rather recommend to just not have a changelog at all.
Another important thing for me is the deprecation notice section. What do I need to look out for in the future? Should I start to migrate to another API soon? Even right now? Or does it have time?
While going through these terrible GitHub release pages, I also found these “New Project Contributors” sections (yeah, for that, they found the time to make a section) annoying. Don’t get me wrong, sure, credit where credit is due. But come on. Soooooo much space for an inefficiently formatted (and also unsorted) list. At least it was easy enough to skip over it.
And then, there are also these changelogs or rather notice documents in general that are infested with multicolored emojis all over the place. My brain’s spam filter kicks in and shoves everything to /dev/null immediately. It’s especially a thing at work.
In my previous work project, we also used the Keep A Changelog Format. That was great. You wouldn’t believe how often I resorted back to that document. At least twice a week, often several times a day. I was very glad that we put in this effort. Of course, writing the changelog took its time, but it was worth every minute and more. Reading a many months old item, it was immediately clear. I was our best customer in that regard.
Now, it’s just the same auto shitshow with MR titles in a rolling date-versioned release scheme. It’s just our team who has to deal with that, though. I think I’m the only one who is not a fan of it.
↳
In-reply-to
»
@lyse Fernwärme it is. %)
⤋ Read More
@movq@www.uninformativ.de Next town, they use Fernwärme from the waste incineration plant to heat the hospital and probably also parts of the neighborhood. I don’t know how good it works, but in the cold months there’s always steam coming out of the manholes along the road through the woods. I very rarely am in this area, but whenever I am, the steam on the side of the road always amazes me.
People think that “more words means more effort” – that used to be true, and it’s the opposite now.
Anyone can make 200 words. The real flex is turning those 200 words into 6.
Regarding software, I wonder when/if programmers will get this memo.
The concept of synthesis is more useful than artificiality in connection with generative media tools. Synthetic fabrics have been used in the garment industry for decades, while nobody complains anymore that synthesized music is inferior to music played on acoustic instruments. So why are synthetic artworks of all kinds routinely dismissed as inferior to human-produced art?
↳
In-reply-to
»
First draft of a file selection popup / widget:
⤋ Read More
@lyse@lyse.isobeef.org Yeah, it probably would look better. I might fix that. It’s just laziness, the implementation was easier this way. 😅
Glad you find it interesting! And honestly, I agree, nobody but me would use this anyway. There are more mature and featureful toolkits out there.
↳
In-reply-to
»
First draft of a file selection popup / widget:
⤋ Read More
@movq@www.uninformativ.de That is really cool! Maybe it would look nicer if the selected entry highlighted the whole row, not just the individual cells in that row without the column spacers. :-? But maybe I’m wrong. Everyone has their own taste.
And no, it’s not pointless at all. I find this really interesting. The videos and photos are perfect for me. Even if I had the source code, I would not use that toolkit, as I’m not a fan of movable windows in TUIs. I want all my own programs to be fullscreen all the time. 8-) Having said that, it’s still an absolutely brilliant source of inspriation that will come in handy one day. So, keep posting. :-)
First draft of a file selection popup / widget:
https://movq.de/v/0955149868/vid-1781094010.mp4
Also makes use of the new Table widget.
How many atomic warheads are active? 12000 or 13000? Who will ssve us from the evil spirits relying on them
↳
In-reply-to
»
@lyse @tftp Someone has pointed out that there’s OpenRsync:
⤋ Read More
Actually, I’m stupid: I’m using the normal rsync on OpenBSD as well.
And regarding OpenRsync’s general usability:
https://marc.info/?l=openbsd-misc&m=178090751524547&w=2
Right now openrsync is limited in functionality and is primarily present
for rpki-client. The limited functionality makes it unusable for generic
use and so any diff or change like the above will not be considered since it
is simply not ready.First problem to solve is to remove the mmap usage in openrsync. After
that modern protocol versions need to be added. Once that is in place one
can start a discussion about using openrsync as a default on OpenBSD.
↳
In-reply-to
»
@movq That's a great effect! 👍
⤋ Read More
@itsericwoordward@itsericwoodward.com I just want to let you know that your mention completion seems to be broken. :-) The URL is duplicated with a comma in between. Actually, the protocols differ. I suspect that you extract all url metadata fields from the feed, not only the canonical one used for hashing (the first one) and join them. I’m not completely sure, I would need to read up on the specs (it’s already past bed o’clock, though), but I guess that there is no explicit rule for picking the mention URL. Without having thought about it too much, I reckon the safest bet is to stick to the hashing URL when in doubt and the URL that was used to subscribe to the feed is not available for whatever reason. The URL from the subscription list is probably even better.
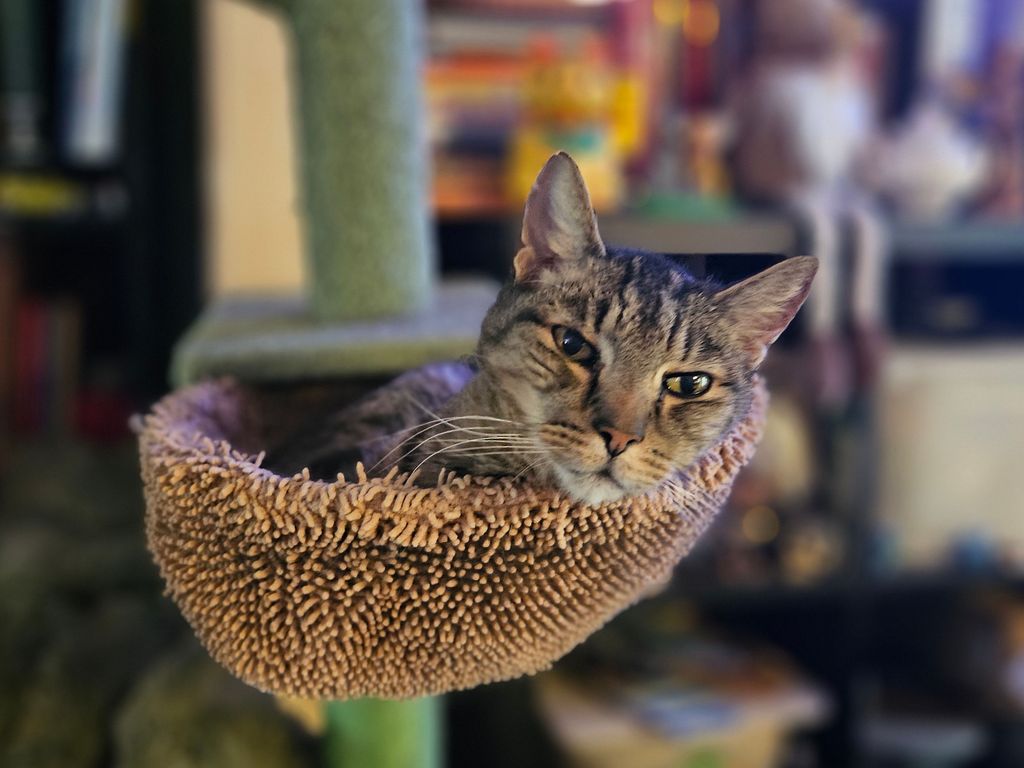
For this week’s (slightly late) #caturday, I’d like to introduce our 4th and final feline resident, the old boy we call Bugsy. He’s been with us for 8 years, and we think he’s 13-14 years old (but he’s not saying).
He used to sound a bit like a cartoon gangster (hence the name), but as the years have passed, he started to sound more like late-stage William Hickey (Uncle Lewis from Christmas Vacation).
He’s our sweet little old man, and he is loved.
↳
In-reply-to
»
Well, that might work... https://codeberg.org/awful-systems/AAA-NO-SLOP.md 🤣
⤋ Read More
@prologic@twtxt.net Fair point, and I don’t plan on doing it myself.
But I also understand raging against the broken social contract(s). It’s like using Iocaine or zip-bombs against the scrapers. I don’t do it, but I understand why someone would feel justified in doing so.
↳
In-reply-to
»
Well, that might work... https://codeberg.org/awful-systems/AAA-NO-SLOP.md 🤣
⤋ Read More
@itsericwoodward@itsericwoodward.com Yes, but is how we want to be behaving. We don’t like something so we go out of our way to be malicious and poison things? I get it though, the hypocrisy is very real here, with burning trees, eating up water supplies, and the massive amounts of energy going into this, but still, this is petulant behaviour and I don’t think it services any useful purpose other than rage and anger.
We came across lots of animals in our woodland. There’s a medieval market this weekend in the neighboring town and they use these targets for the bowmen.
↳
In-reply-to
»
(This settled at about 25k hits on the HTML page now. But only about 11k hits in total on
⤋ Read More
favicon.ico and only around 7.5k hits on the image thumbnails. So I guess that, in reality, it might have gotten around 7k hits. The rest … is probably bots.)
@lyse@lyse.isobeef.org Two emails. 😅 One person asking for the source code, and the author of wcwidth (the library I’m using) contacted me to provide some input. 👌
↳
In-reply-to
»
@prologic As have I. 🤔 I mean, since I left GitHub, I got basically 0 pull requests anyway.
⤋ Read More
@movq@www.uninformativ.de Honestly I think you build the team before you need the PRs 🤔 Start with relationships — people who’ve been using your software, filing good bug reports, asking smart questions. Those are your future maintainers. The PR comes later as a formality, not a tryout 😅
↳
In-reply-to
»
@prologic As have I. 🤔 I mean, since I left GitHub, I got basically 0 pull requests anyway.
⤋ Read More
(#vixabsa) @movq@www.uninformativ.de Honestly I think you build the team before you need the PRs 🤔 Start with relationships — people who’ve been using your software, filing good bug reports, asking smart questions. Those are your future maintainers. The PR comes later as a formality, not a tryout 😅
↳
In-reply-to
»
Okay. I have lost the “battle” against “AI” at work and I will no longer try to “fight” any of it.
⤋ Read More
@movq@www.uninformativ.de Wow, I’m sorry to hear about that. Permanent emergency mode sucks, I’ve been there, and it always felt like drowning.
Fortunately, at my current job, we’ve been given time to keep our technical debt from overtaking the project. Unfortunately, we’ve been forced to use AI (mostly in the form of GitHub Copilot). Of course, now that the tokens cost more than a developer’s salary, they’ve been rethinking that position somewhat. 😁
In my experience, you are 100% correct - even in the best case, AI is a force multiplier. If the code is clean, it can speed you up. But if the code is a mess, it’ll just multiply the mess.
I am about to start working on #IndieConnector version 3, and I need your help! In this post, I describe what I plan to change and would like your feedback and ideas. So if you are a user or you want to use it, please let me know what you would expect from the new version.#kirbycms #getKirby https://maurice-renck.de/blog/2026/planning-indieconnector-3
↳
In-reply-to
»
Now that is an interesting move:
⤋ Read More
@prologic@twtxt.net As have I. 🤔 I mean, since I left GitHub, I got basically 0 pull requests anyway.
Even during my time using GitHub, I noticed that “drive-by PRs” are rarely a good idea. People don’t really know/understand the code or the design principles/goals, so I often turned down PRs. Or I accepted them and was grumpy afterwards. 😅
What does work is having a team of maintainers/devs. The only question is: How do you build such a team if you don’t accept PRs? That’s going to be the interesting part.
↳
In-reply-to
»
You know what this is?
⤋ Read More
@bender@twtxt.net lol, no, please don’t send me a quackton of ducks. 😅 We use BIRD a lot at work, hence this bears some significance for me/us. 😅
You know what this is?

A BIRD bird! 😅
I got it as a gift from a very friendly coworker and she, in turn, got it from Maria Matějka. 😃
Okay. I have lost the “battle” against “AI” at work and I will no longer try to “fight” any of it.
It is simply what people want. They want to use it. And that’s the end of it.
And why do they want it? Because it makes their job easier. And why is that? In very large parts, it’s because we have accumulated a metric fuckton of technical debt due to decades long mismanagement. We were (and are) operating in “emergency mode” all the time. There simply was no time to clean things up or to rethink designs. We always have to go with the cheapest and quickest solution. We are never ahead of things: Earlier this year, I started an initiative and wanted to tackle some issue that I could see coming. I was shut down because this wasn’t “urgent”. Very soon after, this exact thing became that exact problem – but now, there was no time anymore to do it properly because NOW it’s urgent, so, once again, we had to go with a quick and dirty solution.
It’s always like that and I had brought it up again and again. And now we have a huge spaghetti mess that hardly anyone understands anymore.
Nobody – except AI. It can still make some sense of this and, obviously, this is useful to people.
So, any argument I make against AI is completely pointless to begin with. I’m such a fool for not having seen this earlier.
The last argument I made today was: “Look, we already have so much technical debt and spaghetti systems, we really, really must clean this up. If we throw AI on top of this now, it’ll only get so much worse.” And once more, I was shut down. My intentions were “admirable”, but “there’s no time for that”.
Okay. Good luck with that. They’ll keep doing it this way. At some point, it’ll either explode entirely and some poor soul has to clean it up, or it’ll explode and they’ll have no other choice but to throw everything away and start from scratch – assuming they can still afford that.
In other words, none of this about AI, really, nor caused by it. Our department’s massive spike in AI usage is just a symptom of the underlying management issues. And since those aren’t being addressed, nothing will change and this whole mess will only get worse.
(I blame all this on management, because, well, that’s who’s to blame. I do not have a solution for it, though – and assigning blame without constructive criticism always sucks big time. I don’t like doing this. If you had put me into that particular management position, I wouldn’t have been able to solve any of this. The thing is, though, I’m not an expert on management and it isn’t my job – I’m just the “princess” who solves your technical issues.)
↳
In-reply-to
»
@movq It's the "Lyse types the entire HTML by hand" generator. Yes, no kidding. I write articles so rarely, that I can do that once in a while. It's fun to some degree, but also not.
⤋ Read More
Years ago, I used Kate, no, not somebody’s wife, but the KDE Advanced Text Editor, to export source code files and fragments into HTML with syntax highlighting. I think that’s where I got the initial <b> idea from. There were also bucketloads of <span style='color:#644a9b;'> all over the place, even inside <b>. No CSS classes defined upfront, all colors inlined. The final rendering in the browser looked great, but the source code ugly as hell in my opinion. However, I’m thankful for hinting me at <b>. I think this kicked off everything. :-)
↳
In-reply-to
»
@lyse By the way, which site generator are you using? I kind of miss having code blocks with syntax highlighting and that generic yellow highlighting thing is pretty cool, too.
⤋ Read More
@movq@www.uninformativ.de It’s the “Lyse types the entire HTML by hand” generator. Yes, no kidding. I write articles so rarely, that I can do that once in a while. It’s fun to some degree, but also not.
After some time, I finally recorded some Vim macros to insert <b>…</b>, <var>…</var>, <span class=s>…</span> etc. around the tokens. This helped a little bit. But I was still questioning my mental state doing it like that. I also had to fix a bunch of the end tags by hand, because the word movement wasn’t enough or the end movement went too far. Quite the annoying process for sure.
But I think the HTML looks a wee bit nicer and is maybe even semantically a little bit better than having only <span>s everywhere. I find the <span class="whatever"> just soo awfully long. Of course, I never look at the code again, but knowing, that e.g. there is a <b> and it saves so many bytes in comparison, makes me happy. It is a more elegant solution in my opinion. Not by much, but better nonetheless. It’s a matter of simplicity. Admittedly, even I can’t avoid the <span>s alltogether. Oh well. On the other hand, I’m sure that this does not make any difference whatsoever. I bet, nobody and nothing, like a screenreader, analyzes the HTML for that, where this would be truly useful.
Oh! Maybe text browsers, though. It just occurred to me while composing this reply. :-) Haha, I lost my bet quickly. w3m picks up at least the <b> for keywords and builtin types, <u> for filenames and <i> for comments. Yey. No different styles for <var> and <mark>, unfortunately. elinks only renders the bold. It’s cool that I had the right intuition right from the beginning, despite being unable to pinpoint it. :-)
All the <span> hell with common syntax highlighters is a downer for me that keeps me from looking more into them. If I wrote more articles, I might rig something up with Pygments. At least that’s somehow positively connotated in my brain. Not sure if it actually deserves it, but I dealt with that in some loose form (can’t even remember) years and years ago. Apparently, it wasn’t too terrible.
To prepare the table of contents, I used grep and sed with some manual intervention in the end. The entire process can be improved. Absolutely.
You wrote your own site generator, didn’t you?
↳
In-reply-to
»
@movq Thanks. I noticed the
⤋ Read More
<updated> of the feed, too. But for some reason, some articles were suddenly marked as new.
@lyse@lyse.isobeef.org By the way, which site generator are you using? I kind of miss having code blocks with syntax highlighting and that generic yellow highlighting thing is pretty cool, too.
↳
In-reply-to
»
@bender Doing
⤋ Read More
tail -f access.log looks like a Matrix screensaver at the moment. Whoooooosh …
@movq@www.uninformativ.de TLs is cheap, we built hardware encryption modules for AES-256 which TLS still uses so you’re fine 😅
↳
In-reply-to
»
@movq Thanks. I noticed the
⤋ Read More
<updated> of the feed, too. But for some reason, some articles were suddenly marked as new.
@lyse@lyse.isobeef.org Oh, nice. That was quite the ride. :-) And all that because of locales. 😳
But, did I understand that correctly? All Atom feeds were broken, right? Because they all use that same code path with that strftime/strptime dance in it?
↳
In-reply-to
»
@movq Thanks. I noticed the
⤋ Read More
<updated> of the feed, too. But for some reason, some articles were suddenly marked as new.
I wasted my entire weekend on the writeup. If you have way too much time to spare and also are interested in a bug analysis of a software that you don’t even use, I have you covered: https://lyse.isobeef.org/newsboat-time-parsing-bug-analysis/
↳
In-reply-to
»
Over there, on the othernet, I just stumbled upon the question:
⤋ Read More
@arne@uplegger.eu I’m similar… I use “I” most of the time (mostly in planning or trying to focus, ex: “I’m going to do X, then Y”), but I also use “you” when fussing at myself for my perceived faults or mistakes (that’s my “lizard brain”, we don’t get along so well because he’s kind of a jerk).
Oh boy, it was bloody humid this morning. Just around 20°C when we left, but climbing rapidly. The flow of air when walking was okay, but as soon as we stopped, streams of sweat were pouring down on us. Luckily, it was cloudy, but the lack of wind was bad. Now, the sun is out, 29°C will be reached in an hour and I’m glad that the house is still cool. It will be a different story in a few weeks or months. Not looking forward to that at ll.
On the bright side, we saw the first tadpoles of the year and an also first, but sadly dead slow worm that probably some bird dropped on a bench next to the fountain. The fly was stuck to its feast and also cactus. The municipality fixed the railing nicely and we came across a giant patch of great looking fire bugs on the summit.
All in all, a successful stroll through the woods but for the humid heat.
↳
In-reply-to
»
RIP, rsync. https://social.hails.org/@hailey/116657391001259044
⤋ Read More
@lyse@lyse.isobeef.org @tftp@tilde.town Someone has pointed out that there’s OpenRsync:
Since I run OpenBSD on my servers, I actually do use that and have never noticed any incompatibilities with the “normal” rsync.
↳
In-reply-to
»
@movq I'm very curious...
⤋ Read More
it’s “probabilistic” not “deterministic”
Yep, I know. And when I tell that to people and tell them “if we use AI here, we lose the ability to debug this stuff”, then all I get is: “But it’s good enough. We don’t need to debug this. Non-deterministic computing has its use cases.”
But that is just not how I’d like to model/implement our business processes. 🤔 I want something reliable, not “it mostly works”.
↳
In-reply-to
»
@movq I'm very curious...
⤋ Read More
LIke with almost everything “big-tech” has done, it’s not the tech you should not trust, but the companies themselves. For example, accessing and using the models (because let’s face it, they have clusters of much larger and more powerful GPU clusters than we could ever afford to build and own ourselves, at least for now) is fine, but trusting their end-user products/services, not so much.
↳
In-reply-to
»
@movq I'm very curious...
⤋ Read More
@movq@www.uninformativ.de I’m kind of flag you bring thi sup, because you simply can’t. You wouldn’t even be able to in an atypical neural network either (which is what ehse things are anyway). The problem here really isn’t the so-called “AI” (I wish we’d stop calling it AI), but the flawed usage(s) thereof. I believe I even stated earlier in this thread that sometimes it may not do what you expect, it’s “probabilistic” not “deterministic” – those pushing for greater use need to understand this, those not happy with the “push”, should educate the ignorant here (especailly managers pushing for weak, insecure and bad uses).
↳
In-reply-to
»
@movq I'm very curious...
⤋ Read More
@prologic@twtxt.net Ahh, I see. Okay, I’m with you there. On this high level, I can understand how the thing works.
Maybe my wording isn’t good. 🤔 Let’s take a real life example from what we do at work.
There’s this AI chatbot. It gets support requests from users, so the user says something like “I need access to a particular system”. This triggers the bot to “run” the instructions stored in a large Markdown file, like “check if the user is authorized to do this, then issue the following API requests”, and so on. This is essentially like running a little script, except it’s written in natural language (German) and there’s no “script interpreter” but just the AI.
Now, suppose that the AI doesn’t quite do what was intended. There’s some subtle bug. How do you debug this? How do you find out how the AI came to the “conclusion” to run step A instead of step B? And how do you find out how exactly you have to change your prompt so this doesn’t happen again next time?
If this was an actual script/program instead of AI, you could repeat the request and attach a debugger or throw in some printf() or whatever. How do you do that kind of thing with AI? How do you pinpoint exactly what the problem was?
(Or is this just a stupid idea? Do we have to give up that way of thinking when using AI? Is the era of debuggability over?)
↳
In-reply-to
»
@bender Well no. Some of us don't. Let me point you at some research on the subject 😅 Some people don't have an inner monologue
⤋ Read More
@bender@twtxt.net So yeah, no, I do not have an inner monologue at all. Most of the time my inner mind is busy just replaying music or visuals (or at least it used to before I lost my sight, these days it just replays visuals and sounds), but there is never a time when I “talk to myself”, ever, I don’t ever think through something, a problem or an activity and have self-arguments. I just do.
↳
In-reply-to
»
@prologic don’t get mad at me, but the long block of text didn’t address any of my questions. 😜😅
⤋ Read More
@bender@twtxt.net Fine, Let me answer properly and concretely 😅
Would you want your children not to learn anything, because “they have AI”?
No, children still need to learn. That will never change. What they learn however will over time.
Are you OK with your children using the AI for all of their homework?
Yes, frankly I am. Why? Because much of what we teach them in school is utterly pointless.
For example, learning to read Shakespear never taught me anything useful in my life. I regret much of my school years to be honest.
I leanred to read and write, sure. But I learned Math, Science, Computing and how things work on my own by being very curious.
What sense will it make?
That assumes I answered “no”, which I did not. So it all makes perfect sense :D
What kind of future would that bring for them?
This assumes I said “Yes”, which I did :D It will be an itneresting future that’s for sure. I don’t think we can just bury our heads in teh sand and pretend it’s all going to go away, It will not. It will make things very interesting for sure, as we’re already starting to see what’s possible and what’s changeing. For example; ordinary people are using these LLM(s) to write their legal suit and defense in courts with varying levels of success.
Even if AI were to become omniscient, what will it be of the human race then?
I’m not convinced it ever will. In fact, I am not convinced we know how to create true intellience at all.
What would we do?
What would be so different from say an Alien invasion from far superious beings?
What would we do that? Band together and defend humanity?
Serve the AI? Maintain the AI?
That assumes that “AI” will become intelligent and omniscient, which I don’t believe it ever will.
Would we have found the true meaning of life then?
If the meaning of life is to create our own sub-species liken to ourselves, sure, maybe. But is that even a reality? not sure, I doubt it. We barely understand ourselves at the best of times, let alone how our minds works.
To care for AI, Is that it?
How would this be different to caring for a friend, a family member If we could ever truly reate an actual sentient being with real feelings and intelligenace, is there any reason to worry? Could we not be freinds and have mutual goals and form relationships?
↳
In-reply-to
»
@bender Well no. Some of us don't. Let me point you at some research on the subject 😅 Some people don't have an inner monologue
⤋ Read More
@prologic@twtxt.net so, “people with no inner monologue—a condition researchers sometimes refer to as anendophasia”, says the AI. Then “it is not a disorder: lacking an inner voice is simply a different, perfectly healthy way of being human”. Ah, so a condition, but a healthy one. Got it.
Again, I am not talking about a true monologue. If you have never thought “OK, let’s do this!” before engaging on an activity, then alright. Weird, in contrast to the rest of us, hard to believe, yes, but I believe you. Much of the troubleshooting, and creativity that comes with thought involves, well, thoughts. Maybe you are closer to AI than the rest of us, indeed! 🤪😂
↳
In-reply-to
»
@arne This is interesting. Sorry I missed this, I just found this post of yours and wanted to contribute 😅 Here's something interesting about me... I don't ever talk to myself, like ever. I have no, what they call, "inner monologue". Maybe I'm odd, but my wife asked me this very same question a while back and I said the same, there is never anything in my head except ideas, visuals or sounds, sometimes all at once, but never an inner monologue of "talking to myself".
⤋ Read More
@bender@twtxt.net Well no. Some of us don’t. Let me point you at some research on the subject 😅 Some people don’t have an inner monologue
↳
In-reply-to
»
@lyse Thanks! There are a few points in there that I’ll add to my list.
⤋ Read More
@bender@twtxt.net Now that’s an interesting philosophical viewpoint right there. But this assumes that the “AI” we seemingly have available to us today is actually telligent, understands and has cognitive reasoning. It does not. All of these LLM models from big-tech companies like Anthropic, OpenAI, Google, Microsoft, Meta and Alibaba are all just very powerful, very large multidimensional neural networks with attention that are very good at statistical probabilities of ‘what comes next”. I think we get really upset over the wrong things sometimes. We need to continue to be upset that these 🤬 companies have basically destroyed any meaningful value of the concept of Copyright and Intellectual Property and Works of art. The so-called “AI” we have today is just a tool. Can you say for certain that the typewriter and the computer ruined our ability to write? Perhaps yes, but we still learn how to do so, likewise, I still think that learning to write code, research, read and write are all valuable skills to learn. Later on once you have the basics, you can defer some of the “tedious” work to these models, because frankly, they’re far better at inferencing and pattern matching than you or i will ever be, not because they’re better at pattern-matching per se, but because they have been trained on a very large corpus and they are much much faster at doing the same basic things we are far superior at.
↳
In-reply-to
»
@lyse Thanks! There are a few points in there that I’ll add to my list.
⤋ Read More
@prologic@twtxt.net let me ask you this. Would you want your children not to learn anything, because “they have AI”? Are you OK with your children using the AI for all of their homework? What sense will it make? What kind of future would that bring for them? We need to analyse the repercussions from all angles, even if AI were to provide absolutely flawless answers every single time. Even if AI were to become omniscient. What will it be of the human race then? What would we do? Serve the AI? Maintain the AI? Would we have found the true meaning of life then? To care for AI. Is that it?
↳
In-reply-to
»
@movq Thanks. I noticed the
⤋ Read More
<updated> of the feed, too. But for some reason, some articles were suddenly marked as new.
Aha, yesterday’s newly added support for LC_TIME to render localized timestamps also broke the feed parsing with my LANG=de_DE.UTF-8 and LC_CTYPE=de_DE.UTF-8 environment. :-)
Atom feeds make use of RFC 3339 timestamps. They are first converted into RFC 882 timestamp representation, which is the one that RSS feeds use. However, this conversion now results in localized RFC 882 timestamps, which cannot be parsed into Unix timestamp numbers via curl_getdate(…). I bet that it doesn’t know about the localization at all and expects English month and weekday names. Looking at its docs, I reckon that function was selected because of its myriad of supported timestamp formats: https://curl.se/libcurl/c/curl_getdate.html RFC 3339 is not included, though, hence the transformation up front.
The intermediate Item objects in the parser domain use std::string for the timestamp representation. This isn’t all that silly, because Newsboat supports all sorts of different feed formats with different timestamp formats. These RFC 883 timestamps are centrally parsed into time_t.
Speaking of time: It’s time to go to bed after this late bug hunting fun. :-)