↳
In-reply-to
»
The original twt is unavailable. It may have been edited or deleted, or is from an unknown or muted feed.
⤋ Read More
@Sumomo@sumomo.neocities.org if you’re looking for a great static site generator/publishing tool by the way have a look at my project ZS
↳
In-reply-to
»
@movq https://movq.de/blog/postings/2026-08-05/0/POSTING-en.html Very interesting! I basically never analyze binary files, but this were some great thoughts on that subject. I hope to remember them when I find myself in the situation to look at binaries more closely.
⤋ Read More
@lyse@lyse.isobeef.org I don’t do it that often, either. But when I do, I always wanted to have such a tool. :-) And since it turned out super easy to “implement” … Why not.
↳
In-reply-to
»
The author of the Xfce Wayland compositor on LLMs:
⤋ Read More
Most of this insane power consumption happens during the models training, so the additional cost of prompting, is minimal. Facebook invented cool ways to exted the environmental damage far beyond the training stage, by dumping the dirty data center water into nearby water sources, but that’s more so a Facebook problem, than a fault of AI.
I would still never waste my own money, paying for any AI subscriptions that my employer doesn’t already pay for, no matter if we use them, or not.
I am also against aggressive scraping and taking everything as training data, disregarding the authors wishes and license. I allow it on my website, mostly as proof that no matter how much they scrape my stuff, the real me remains both a superior webdev and artist.
I am well aware this makes me come across really egotistical, especially after developers far better than me, embraced vibe coding, arguably way too much. To give an example, all attempts to get Microsoft Copilot, that’s embedded into SharePoint, to generate an extension/uBlock filter to make SharePoint revert to the old superior UI failed, but I was able to do that in three lines of code ( https://thecanine.smol.pub/ublock-filters ), in half an hour, despite me never seeing the code of that page before. After a few of these comparisons, it is increasingly hard to see most of these tools, as my replacement.
I am not even going to talk about the people trying to imitate my art style with AI, until they can show me a result where all the squares are the same size, in a grid and actually square.
↳
In-reply-to
»
The author of the Xfce Wayland compositor on LLMs:
⤋ Read More
@movq@www.uninformativ.de @david@daiwei.me @thecanine@twtxt.net Yeah, I’m with you. It is just a tool, but it’s a tool that burns rainforests and boils lakes when you use it, owned by some incredible awful human beings, and built on the backs of an increasing number of crippling mass-scraping campaigns. These costs are just too high.
I have to use it at work, but it’s “the new norm” in software, so I’m hoping to use it just enough to get by until either 1) the bubble pops (and we don’t have to use it anymore) or b) I retire. And actually, 1) happened for a minute back in June when M$ increased the prices of tokens, so it’s certainly possible it could happen again.
All that having been said, I think the technology itself has some interesting uses, and I’m looking forward to the day when I can host some open source models on local hardware. But I can wait.
And yes, the site is unreadable on mobile, which is kinda wild for 2026. 🦆
The author of the Xfce Wayland compositor on LLMs:
https://www.spurint.org/journal/2026/07/llms-and-xfwl4
He openly admits that he’s totally aware of the issues. But he simply doesn’t give a fuck.
This is (part of) why this whole AI/LLM topic makes me so sad and angry: Many people in tech are such a disappointment. You’re smart and intelligent, but you don’t give a fuck about anything. “It’s just a tool.”
↳
In-reply-to
»
The original twt is unavailable. It may have been edited or deleted, or is from an unknown or muted feed.
⤋ Read More
@david@daiwei.me Absolutely insane! For almost all the tools I always need two hands for sure. I can’t imagine using just a single one. And then his stuff turns out 100 times better than I could ever do.
There are advantages with just a single hand, though. I cut myself in the finger with scissors earlier. How stupid is that! :-D
↳
In-reply-to
»
Dunno if anyone will find this interesting... But some ~6 months or so ago I experimented briefly with creating a whole bootloader + kernel + userland -- Basically an entire OS in the Mu programming language (which as you know I also designed and created) -- 6 months later I've worked on it some more after spending the last week working on improvements to Mu itself, which is now able to compile itself with its own Mu implemented compiler and now have an os/arch backend called
⤋ Read More
muos/amd64 that boots into a running shell, with a tiny little vfs, UNIX-like semantics, syscalls, read/write, etc. It works pretty nicely, and aside from a small Assembly "nucleus", most of the Kernel and Userspace is written in Mu.
I just taught the scc SLOC tool I use how to detect and recognize the Mu programming language. So it’s actually a bit worse than your estimate. It’s more like ~60/30 at the moment:
>>> mu = 1445
>>> asm = 2365
>>> T = mu + asm
>>> mu / T * 100
37.9265091863517
>>> asm / T * 100
62.07349081364829
↳
In-reply-to
»
Advertise in ChatGPT | Hacker News Seriously?! 😳 wut da actual fuq?! 😱
⤋ Read More
@prologic@twtxt.net Our company is paying a shitload of money for all these (different) AI tools … I’m probably not allowed to tell you the exact number, but it is a lot. The only other way would be to lay off employees, so we can pay even more for AI. (Needless to say, that would be the worst possible move.)
For a private person, $20 a month is also pretty expensive, isn’t it? And then assume that you maybe need more than one AI tool. You’re quickly up to $50 a month or much more. This isn’t something that I, as a private person, will ever be willing to spend for this kind of stuff.
“AI” is just expensive as fuck. On every level. They will have to (ab)use every possible way to squeeze more money out of it, and that includes ads and what not.
I finally built a prototype of a marking gauge with a cutter wheel out of some scraps.
https://lyse.isobeef.org/tmp/streichmassprototyp-mit-messerrad/
It had been a long time in coming, I bought some replacement cutting wheels three years ago for exactly that purpose. I also found out that I need more M3 countersink bolts for future marking gauges that I want to make (maybe two or three more). Luckily, I had exactly one. I thought I got way more than that, but M3 is very, very scarce in my collection. My M3 bolt was barely long enough to attach the cutting wheel to the bar. But it’s okay for the prototype.
I was pleasantly surprised that I managed to drill the 2.5mm diameter hole almost perfectly in center in the 8mm diameter aluminium round bar. Center finder, drill press and vise with a vertical prism for the win!
I knew upfront that the M5 steel bolt to lock the bar in place definitely needs to be replaced with a brass or aluminium one (maybe with a knurled head). Otherwise, it cuts into the aluminium bar and leaves ugly marks. These burrs might even scratch the workpiece. But, of course, I don’t have any brass on hand either. Alternatively, I swap out the aluminium bar for a steel or even stainless steel one. Stainless might be tricky to precisely drill and tap, though.
I already learned a few things by making this prototype. The final wooden fence can be even a bit bigger. This round thing behind is also too short, I’d like it to be a tad longer and thicker. The final one will be made from hardwood, not spruce. Other than that, it’s great and already more practical than my store-bought marking gauge with its round fence. This only causes the tool to roll around on the workbench. Or even roll off. Stupid design.
↳
In-reply-to
»
@prologic Hmmm, I have no idea how to solve that problem. 😅 Some
⤋ Read More
jenny stuff aside, I received zero bug reports or code contributions since leaving GitHub in 2018.
@prologic@twtxt.net Oh, yes, just for clarity: This wasn’t a “pro GitHub” argument. 😅 I won’t go back there (or to another “forge”).
I think we’re totally on the same page: Decentralized Git hosting is good, but we haven’t solved the “collaboration” part yet. Or rather: We have to modernize it. The tools are already there, but (many) people don’t want to use them and think they’re clunky.
I really think I should go back to Java.
Writing programs in Python is so exhausting. I want a compiler and I want static typing. No, linters and type checkers and IDEs are not good enough. Compilers catch way more errors in advance.
Rust is also exhausting. They’re constantly adding language features and, at the same time, the runtime library remains tiny and you need 3rd party libraries for everything. Many of those are still at version 0.x (SemVer!) and you can’t rely on anything. Often times, you need the latest Rust nightly compiler.
Go is … I don’t like it. And huge binaries.
I like C as a language, but it’s too fragile. I want to have a proper HashMap every now and then.
None of the above have good GUI libraries, at least not on Linux.
And then there’s Java. This is my fractal renderer that I wrote over 17 years ago:
https://movq.de/v/fcd3c4e557/vid-1784121825.mp4
It’s fast. It has a GUI with custom widgets and those weren’t even hard to make. It still works without changing a single line of code. The source code files have timestamps from 2009 and I just noticed that the JAR file I’m using in the video was compiled in 2010.
Java as a language is relatively easy to learn and to master. There are few surprises. The source code organization with packages is good. Java API docs are clear and well written.
The JVM ramp-up times have improved considerably:
https://movq.de/v/e7314e521e/vid-1784121998.mp4
This isn’t like the Dark Ages anymore. Might even be usable for some CLI tools.
The only thing where Java really sucks is anything close-ish to the kernel. Try issuing an ioctl() … I couldn’t have made my TUI framework in Java, but then again, I wouldn’t have needed to because Swing already exists and it just works.
Windows NT 4 didn’t have a Device Manager. You know, this thing right here that got introduced with Windows 95:

And that’s super awkward in NT4.
You know what doesn’t have a Device Manager, either? Linux. Why? 🤔 Isn’t this one of the most useful system tools? It gives you an overview of the devices in your system and tells you which driver is used for them. Linux could really use such a tool, I think? 🤔
(There are programs like “hardinfo” and I remember ancient KDE providing such a tool, but they’re all an afterthought. Hardly integrated into the overall system.)
This is a neat tool for comparing several public DNS resolvers (some of which were new to me) on various criteria; includes a speed test. https://evilbit.de/dns-resolver-guide.html
So I’ve been working on GoNIX the last few days… Which is derived from µLinux – At least it’s entire build process. GoNIX however has a 100% Go userland, including the init process, package and service management.
Now… As an experiment, because I was able to make much process on enhancing the build tools and package management, I decided to see if I could build a “Desktop” Gui of sorts…
I still wanted it to be fairly minimal and lightweight. So I went with wayland (of course) and labwc and yambar. So far I’m liking the result 👌 42 packages in the wayland-desktop meta port. Not too bad. Not sure if I can slim that down anymore… But trying to avoid Mesa/GL as that drags in far too much “cruft”.
↳
In-reply-to
»
@lyse Ah, you mean the categorization. Yeah, that would never work in Windows, at least not without having a centralized package manager (so there’s one authoritative source of which program belongs into which category).
⤋ Read More
@movq@www.uninformativ.de That’s right, way harder than centrally managed. They even didn’t reach concensus over the main folder: “Alle Programme, “Alle Programme (x86)”, “All Programs”, “All Programmes”, etc. Anyway.
For class 11 (or maybe already in 10, I don’t remember exactly) we could choose either between traditional maths class with a graphical calculator or “Mathe mit CAS”. There were two teachers in my entire school who were able to teach the latter. It was also fairly new at the time I believe. Certainly unheard of for a „allgemeinbildendes Gymnasium“, maybe the technical ones were already offering it for some time, not sure. It was clear to me that I would take the maths with CAS class.
Each kid had to buy their own Cassiopeia A-Something. I don’t know how much that thing was (definitely more expensive than a graphical calculator) and whether the school subsidized that in any form. But it was slow and underpowered as hell. We rarely used it in class nor for homework (most if not all had already a desktop at home). Typically, when we worked with the CAS, we sat down on the desktop computers. Our class took place in one of the two computer rooms. The desktops were placed on the three sides (left, right, back, facing the walls or windows) and the regular school desks were in the middle. Since there were more pupils than desktops, we always shared. Nowadays, we call it pair programming. ;-)
For the exams we had the “mandatory part” (Pflichtteil) without any tools. Once we finished that and handed the papers to our teacher, we were then allowed to boot up our Cassiopeias and work with them for the second part. Before the exam started, everyone had to show the teacher that they reset their small computer to factory settings. This second part was called „Wahlteil“. But you had to do it in order to pass. So, I never understood the choice of this term. Maybe it’s because the first part is the exact same for everyone (graphical calculator and CAS class), but the second part was definitely different for the two classes. Each suited to their tools.
After one or two exams, it became clear that the Cassiopeia was far from ideal. So, we took the second part at the desktop computers from then on. Our teacher unplugged the network cables himself to avoid cheating. Each computer had an “HDD Sheriff” running that reset the disk at startup. There was also an issue that the personal user accounts were affected by that. Sometimes all your data were lost. If you were lucky, they were still there. So, we saved our Maple project to local disk (if the computer didn’t crash in between, that was no problem) and at least eventually before leaving the classroom, we then also saved it on the server. For that, the teacher quickly plugged in the cable, we saved, and then the cable was unplugged again immediately. Oh, and everybody used their USB sticks, too.
All in all, this Cassiopeia A-* was quite a useless purchase. :-D I’m not sure if I still have it. At least I thought several times about giving it to the flea market. Don’t know if I did or not.
Every now and then, I think that I have carefully proof-read my message enough times and hit the “Add message” button in tt. But then, in the message tree, I spot another missed typo. My process is then to go to my twtxt.txt and fix it by hand. However, I still have to clean up tt’s cache. This is rather tidious:
- Recall the
sqlitebrowser ~/.local/share/twtxt/tt2.sqlitefrom my shell history.
- Switch to the “Browse data” tab.
- Go to the
messagestable and wait a second or two until it’s loaded.
- Sort by the
created_atcolumn twice, so that I get descending order.
- Select the first message, which is typically the one in question.
- Find the “Remove currently selected row” button in the tool bar.
- Commit the changes.
- Close sqlitebrowser.
So, I finally implemented the removal of messages from the cache in tt. I can now hit d and confirm the removal. Bam! Should have done that ages ago!

Next up is the search, I think.
The concept of synthesis is more useful than artificiality in connection with generative media tools. Synthetic fabrics have been used in the garment industry for decades, while nobody complains anymore that synthesized music is inferior to music played on acoustic instruments. So why are synthetic artworks of all kinds routinely dismissed as inferior to human-produced art?
↳
In-reply-to
»
@movq Related reading (if you're interested): Let's Talk about LLMs by James Bennett
⤋ Read More
@itsericwoodward@itsericwoodward.com That DORA quote is 🤯 — and it perfectly explains why AI coding tools terrify me in certain contexts. Dropping Copilot into a codebase full of technical debt isn’t gonna fix the debt, it’s just gonna write more of it faster 🤣 Fred Brooks would be nodding his head right now 🙏
↳
In-reply-to
»
@movq Related reading (if you're interested): Let's Talk about LLMs by James Bennett
⤋ Read More
(#xbh2sbq) @itsericwoodward@itsericwoodward.com That DORA quote is 🤯 — and it perfectly explains why AI coding tools terrify me in certain contexts. Dropping Copilot into a codebase full of technical debt isn’t gonna fix the debt, it’s just gonna write more of it faster 🤣 Fred Brooks would be nodding his head right now 🙏
↳
In-reply-to
»
Apologies to anyone who's seen an uptick in twtxt pings from me today... I've been working on shoe-horning my twtxt reader (TwtStrm) into my editor (TwtKpr, aka the
⤋ Read More
express-twtkpr npm library), and it kind ran amok a few times. So again, sorry - I've added a minimum 10-minute cool-down period between pulls which should help (I hope 🙂).
@itsericwoodward@itsericwoodward.com Excited to see twtxt tooling in the Node ecosystem! Any plans to implement the Twtxt v2 extensions? Things like Twt Hash + Subject (proper threading), Multiline, etc. — all documented at https://twtxt.dev 👀
↳
In-reply-to
»
@movq I'm very curious...
⤋ Read More
It’s one of the reasons in fact I’ve been working on bob so I have a very concrete and strong foundation for how these things work, how they behave and how bad or good they can be. I am on-purpose building bob to be not only a decent coding tool and general task completion tool, but with serious security boundaries, sanitation, auditing and compliance. If I’m going to succeed at building autoonmous agents that can cope with a wider array of varying inputs (mostly natural language, some structural language) then it needs to be both a) Safe and b) Robust
↳
In-reply-to
»
@lyse Thanks! There are a few points in there that I’ll add to my list.
⤋ Read More
@bender@twtxt.net Now that’s an interesting philosophical viewpoint right there. But this assumes that the “AI” we seemingly have available to us today is actually telligent, understands and has cognitive reasoning. It does not. All of these LLM models from big-tech companies like Anthropic, OpenAI, Google, Microsoft, Meta and Alibaba are all just very powerful, very large multidimensional neural networks with attention that are very good at statistical probabilities of ‘what comes next”. I think we get really upset over the wrong things sometimes. We need to continue to be upset that these 🤬 companies have basically destroyed any meaningful value of the concept of Copyright and Intellectual Property and Works of art. The so-called “AI” we have today is just a tool. Can you say for certain that the typewriter and the computer ruined our ability to write? Perhaps yes, but we still learn how to do so, likewise, I still think that learning to write code, research, read and write are all valuable skills to learn. Later on once you have the basics, you can defer some of the “tedious” work to these models, because frankly, they’re far better at inferencing and pattern matching than you or i will ever be, not because they’re better at pattern-matching per se, but because they have been trained on a very large corpus and they are much much faster at doing the same basic things we are far superior at.
↳
In-reply-to
»
@lyse These days (and it’s been like that for a while), almost everything is loaded on-demand depending on which hardware the OS finds, so you can simply copy all your files with
⤋ Read More
cp -a, install a bootloader, adjust some minor things /etc/fstab, done. Well, maybe not “done”, but it’s easy to sort out the remaining stuff afterwards.
@bender@twtxt.net It’s been a while (6.5 years) since I’ve done this. I’d do it like this:
- Boot some Linux from a USB stick on the new machine. Preferably Arch Linux, since that is what I’m running and that’ll make the upcoming chroot easier.
- Partition the new disk, create LUKS devices, filesystems, …
- Mount the new filesystems and copy all data (user data and the system itself – everything). Do this either over the network or by hooking up the old disk directly.
- chroot into the new system (Arch has an
arch-chroottool for that which is used during normal installation, if I’m not mistaken). Inside the chroot, install the bootloader.
- Do some fixups, like adjusting
/etc/fstabor/etc/crypttab.
And I think that should be it. 🤔
↳
In-reply-to
»
They are all very nice @lyse! You truly need some sort of easy to navigate website with them all, categorised, and such… A robot can dream, right? :-)
⤋ Read More
¡Muchas gracias @bender@twtxt.net! I was also thinking about categorizing them a few years ago. But it’s so much work. I would have to tag every photo on its own. My use case goes more towards “give me all albums with squirrels”, though. Let’s see. I would need some tooling for easy tagging first. And then, the question is, which categories do I want to have to begin with?
Another AI rant:
One of the “key features” of LLMs is that you can use “natural language”, because that is supposed to be easier than having to learn a programming language. So, when someone says to me, “I automated this process using AI!”, what they mean is: They have written a very, very large Markdown document. In this document, they list what the AI is supposed to do.
In prose.
This is a complete disaster.
Programming and programming languages have one crucial property: They follow a well-defined structure and every word has a well-defined meaning. That is absolutely brilliant, because I can read this and I can follow the program in my head. I can build a mental model. I can debug this, down to the precise instructions that the CPU executes. This all follows well-defined patterns that you can reason about.
But with these Markdown files, I am completely lost. We lose all these important properties! No debugging, no reasoning about program flow, nothing. It’s all gone. It’s a magic black box now, literally randomized, that may or may not do what you wanted, in some order.
People now throw these Markdown files at me … and … am I supposed to read this? Why? It’s completely random and fuzzy.
Sadly, these AI tools are good enough to be able to mostly grasp the authors intentions. Hence people don’t see the harm they cause, because “it works”.
We already have a ton of automations like this at work: Tickets get piped through an LLM and these Markdown files / prompts determine what will happen with the ticket, and maybe they trigger additional actions as well, like account creation or granting permissions. All based on fuzzy natural language – that no two humans will ever properly agree on.
Jesus Christ, we’re now INTENTIONALLY bringing the ambiguity of legal texts and lawyers into programming.
Using natural language is NOT easier than using a programming language. It is HARDER. Have you people never read a legal contract? And that stuff can STILL be debated in a court room.
I can’t begin to comprehend why we, tech folks, push this so hard. What is wrong with you? Or me?
(And, once again, we’re ignoring other factors here. LLMs use a ton of energy and ressources, that we don’t have to spare. It’s expensive as fuck. It doesn’t even run locally on our servers, meaning we give all these credentials and permissions to some US company. It’s insane.)
↳
In-reply-to
»
@lyse
⤋ Read More
@lyse@lyse.isobeef.org Clearing legally? You must have an amazingly efficient legal team – there’s like 10 new tools every week. 🤣
↳
In-reply-to
»
@lyse
⤋ Read More
@movq@www.uninformativ.de No, just the damn training. For the tools, they always want the latest shit available. The company isn’t quick enough in purchasing and legally clearing the latest models, services, etc., they say. Other than that, they seem to be happy.
↳
In-reply-to
»
@lyse Yes, and that’s why I’m 100% convinced that we’ll see a massive brain drain in a couple of years. This will affect young people even more, because they don’t have all the “old” knowledge to fall back on.
⤋ Read More
even our hippest AI enthusiasts found it absolutely terrible
Does this refer to the training course or to the tools themselves? 🤔
↳
In-reply-to
»
Eehhh, what the hell is going on here!?
⤋ Read More
@lyse@lyse.isobeef.org Yes, and that’s why I’m 100% convinced that we’ll see a massive brain drain in a couple of years. This will affect young people even more, because they don’t have all the “old” knowledge to fall back on.
It’s concerning, I’ve warned about it many times, nobody listens.
I think the best thing one can do is explicitly not use any AI tools but keep your actual skills intact. Might be out of a (good) job for a while, but once this bubble bursts, this is who is going to get hired again. (I think.)
And considering how insanely expensive all this is, I’m still (mostly) convinced that the bubble will actually burst. This stuff just isn’t sustainable.
… or I might be wrong. And if so, I see an even darker future that I don’t want to put into words right now.
↳
In-reply-to
»
Eehhh, what the hell is going on here!?
⤋ Read More
@lyse@lyse.isobeef.org AI result ahead, feel free to ignore.
I “asked” the AI at work the same question out of morbid curiousity. It “said” that SQLite converts that integer to floating point internally on overflows and then, when converting back, the x86 instruction cvttsd2si will turn it into 0x8000000000000000, even if the actual floating point value is outside of that range. So, yes, it allegedly actually saturates, as a side effect of the type conversion.
I couldn’t find anything about that automatic conversion in SQLite’s manual, yet, but an experiment looks like it might be true:
sqlite> select typeof(1 << 63);
╭─────────────────╮
│ typeof(1 << 63) │
╞═════════════════╡
│ integer         │
╰─────────────────╯

sqlite> select typeof((1 << 63) - 1);
╭──────────────────────╮
│ typeof((1 << 63) ... │
╞══════════════════════╡
│ real                 │
╰──────────────────────╯
As for cvttsd2si, this source confirms the handling of 0x8000000000000000 on range errors: https://www.felixcloutier.com/x86/cvttsd2si
The following C program also confirms it (run through gdb to see cvttsd2si in action):
<a href="https://yarn.girlonthemoon.xyz/search?q=%23include">#include</a> <stdint.h>
<a href="https://yarn.girlonthemoon.xyz/search?q=%23include">#include</a> <stdio.h>

int
main()
{
    int64_t i;
    double d;

    /* -3000 instead of -1, because `double` can’t represent a
     * difference of -1 at this scale. */
    d = -9223372036854775808.0 - 3000;

    i = d;
    printf("%lf, 0x%lx, %ld\n", d, i, i);

    return 0;
}
(Remark about AI usage: Fine, I got an answer and maybe it’s even correct. But doing this completely ruined it for me. It would have been much more satisfying to figure this out myself. I actually suspected some floating point stuff going on here, but instead of verifying this myself I reached for the unethical tool and denied myself a little bit of fun at the weekend. Won’t do that again.)
Heyy 04866, regarding grub, you should have checked your grub config file before installing it, never rely on distro’s tools. See if your grub config matches your intention and install it, if not, tweak it until it’s fine.
You should study your tools if you’re planning to FAFO with them. Now use a live USB and see if the grub files are missing something, or just learn how grub works.
Just learned this nice little life-hack
for disconnecting MC4 Solar connectors 👌 Works really well! And I don’t have to buy a special little MC4 assembly tool 🥳
↳
In-reply-to
»
The original twt is unavailable. It may have been edited or deleted, or is from an unknown or muted feed.
⤋ Read More
@lyse@lyse.isobeef.org A-ha! That means you haven’t spent enough time with these tools! Go on, try it! (If you don’t, we’ll fire you.) I’m sure you’ll like it!

↳
In-reply-to
»
Can anyone recommend a command-line SQL query formatter? Unfortunately,
⤋ Read More
sqlparse is also unsuitable for me: https://github.com/andialbrecht/sqlparse/issues/688
I’m supporting incremental SQLite schema changes to just upgrade from an older database version to whatever the current software version supports. In the past, I already noticed that this is quite expensive in unit tests when each test case runs through the entire schema patches and applies them one by one.
To speed up test execution I now decided that I finally go through the troubles of maintaining both a set of incremental patches and a full schema setup in one go. A unit test verifies that both ways end up with the same structure. This gives me a set of SQLs to check the structures:
SELECT type, name, tbl_name, sql
FROM sqlite_schema
ORDER BY type, name, tbl_name
Unfortunately, the resulting CREATE TABLE SQL queries are formatted differently, depending on whether the full schema was set up in one big step or the structure had been modified with ALTER TABLE. Mainly, added columns are not on their own lines but appended in one physical line. That’s why I wanted an SQL formatting tool. Since I didn’t find one that works decently, I’m now doing some simple string manipulation. Joining consecutive whitespace into a single space character, removing spaces before commas and closing parentheses and spaces after opening parentheses. This works surpringly good enough. Of course, if it fails, the “diff” is absolutely horrendous.
Now for the cool part, my test execution dropped from around 5:05 minutes to just 1:32 minutes! I call that a win.
I just stumbled across PRAGMA table_info('tablename') https://sqlite.org/pragma.html#pragma_table_info, PRAGMA foreign_key_list('tablename') and friends. I guess, I have to play with that, now. It’s probably much better to use than the SQL text approach.
↳
In-reply-to
»
@kiwu Sorry, I have two functional brain cells left in my brain, and I'm not sure if you're asking What am I putting in it, as in a) when making some? Or as in b) when consuming/serving it?
⤋ Read More
@rdlmda@rdlmda.me it is called, in Spanish, “the mother”. It is created through a bit (not by much) effort, and kept as a starting point. Just like Asian cuisine has dishes that never cool, always cooking leaving always a base on it.
How do you think a lathe (and just about any tool, etc.) is done? Yup, in part by using a lathe. 😅
↳
In-reply-to
»
The original twt is unavailable. It may have been edited or deleted, or is from an unknown or muted feed.
⤋ Read More
@movq@www.uninformativ.de I know it’s crazy right 🤯 these things are just tools. They’re not even remotely intelligent at all. In fact they are actually quite stupid. If you feed it garbage you get garbage out! The only interesting thing is that you get somewhat intelligible garbage out 😂
HEY! I think we all noticed that privacy is dying. Government and corporate entities around the world are building the laws and tools to track you, from everything you write, to the media you consume, to where you drive your car and the people you associate with. Gopher I believe Is one of the last bastions of freedom away from what I call “Corpo web”. GopherSpace is free, I wrote my client so I know it’s safe, and I can route my traffic over tor or any proxy of my choosing. I think we should use gopher as a means to communicate and get out of the modern corpo web because soon everything you do and say on the modern web or possibly corporate owned devices is under scrutiny, even more so than it ALREADY IS. Right now I can use tor and my custom gopher cli to communicate privately here. With the ways the laws are going they are going to implement things like age verification to track you and they’ll deem privacy focused open source software as tools for circumventing these rules. It’s a slippery slope. I need to stop writing before I sound really crazy.
does magical.fish’s admin still come around here or not? it seems that the stock prices tool is broken
The modern world seems to want to separate the concepts of beauty and utility. We’re fine with having things that are aesthetic but don’ do anything useful, while the tools of society that get work done are often very ugly–visually, socially and metaphorically. Beauty without utility is worthless; utility without beauty is meaningless. We can’t treat them independently.
↳
In-reply-to
»
@lyse
⤋ Read More
@movq@www.uninformativ.de Sorry, I meant the builtin module:
$ python3 -m pep8 file.py
/usr/lib/python3/dist-packages/pep8.py:2123: UserWarning:

pep8 has been renamed to pycodestyle (GitHub issue #466)
Use of the pep8 tool will be removed in a future release.
Please install and use `pycodestyle` instead.

  $ pip install pycodestyle
  $ pycodestyle ...
I can’t seem to remember the name pycodestyle for the life of me. Maybe that’s why I almost never use it.
Since I used so much Rust during the holidays, I got totally used to rustfmt. I now use similar tools for Python (black and isort).
What have I been doing all these years?! I never want to format code manually again. 🤣😅
mu (µ) now has builtin code formatting and linting tools, making µ far more useful and useable as a general purpose programming language. Mu now includes:
- An interpreter for quick “scriptinog”
- A native code compiler for building native executables (Darwin / macOS only for now)
- A builtin set of developer tools, currently: fmt (-fmt), check (-check) and test (-test).
↳
In-reply-to
»
@lyse Yeah I remember you said some days back that your interest in compilers was rekindled by my work on mu (µ) 😅
⤋ Read More
@lyse@lyse.isobeef.org I can tell you this right now, writing assembly / machine code is fucking hard work™ 😓 I’m sure @movq@www.uninformativ.de can affirm 🤣 And when it all goes to shit™ (which it does often), man is debugging fucking hard as hell! Without debug symbols I can’t use the regular tools like lldb or gdb 😂
New repository: aquilax/nfo-tools - Tools for managing kodi nfo files
↳
In-reply-to
»
Hey EU friends 👋 wtf happened to the EU Internet today for about 40 minutes or so?
⤋ Read More
@prologic@twtxt.net I’ve been awake at that time, didn’t notice anything. 🤔 Where was that BGP analyzer again … 😅 There’s a tool that keeps track of these things, right? I forgot what it was.
↳
In-reply-to
»
H… Ho… How have I not heard about vim-tagbar before? 😳
⤋ Read More
@lyse@lyse.isobeef.org Yeah, well, given that I didn’t need this for such a long time, it’s probably not an essential tool. 😅
I’ve often wanted to have an outline of text documents, though, and tagbar/ctags can do that as well:
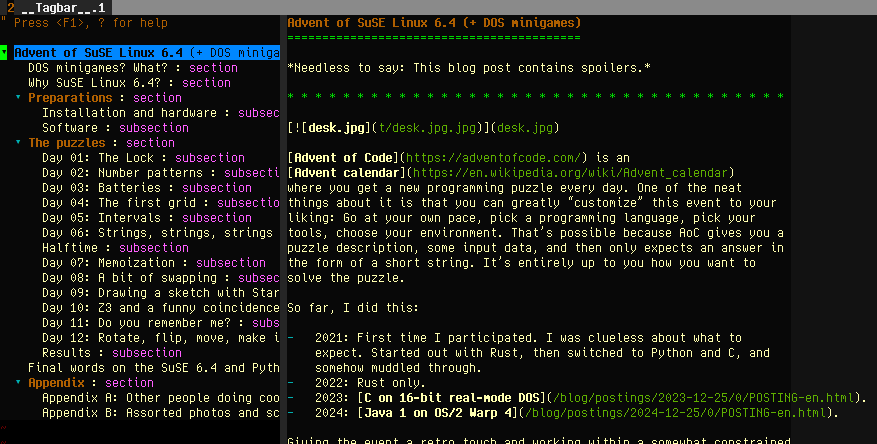
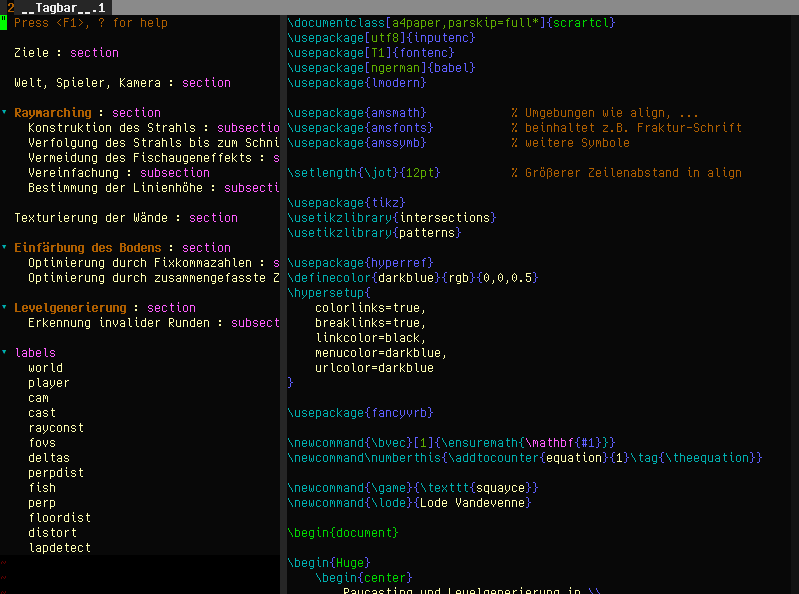
This isn’t as powerful as the “Navigator” tool in StarOffice/LibreOffice (which can be used to rearrange the document), but still pretty useful:
https://www.uninformativ.de/blog/postings/2024-05-23/0/so31.mp4
idk if magical.fish admin reads this chat but it seems that the stock price tool spits an error
↳
In-reply-to
»
Hmmm 🧐 I'm annectodaly not convinced so-called "AI"(s) really save time™. -- I have no proof though, I would need to do some concrete studies / numbers... -- But, there is one benefit... It can save you from typing and from worsening RSI / Carpal Tunnel.
⤋ Read More
@prologic@twtxt.net AI is slot machines for coders:
- “Before starting tasks, developers forecast that allowing AI will reduce completion time by 24%. After completing the study, developers estimate that allowing AI reduced completion time by 20%. Surprisingly, we find that allowing AI actually increases completion time by 19%–AI tooling slowed developers down.” https://metr.org/blog/2025-07-10-early-2025-ai-experienced-os-dev-study/
- “Stack Overflow data reveals the hidden productivity tax of ‘almost right’ AI code”: https://venturebeat.com/ai/stack-overflow-data-reveals-the-hidden-productivity-tax-of-almost-right-ai-code
The same intermittent reward operant conditioning that gets people addicted to gambling and thinking that if they follow certain rituals they’ll win “next time” drives people’s beliefs that AI tools are making them more productive when they’re making them less productive. I’m going to guess that a side effect of this is that people think they’re typing less when in the longer term they’re typing the same amount or more when you factor in the productivity loss (as far as I’ve read the studies don’t measure this so I’m only guessing).
People are also being rapidly de-skilled by this technology: the more they use it, the more their actual skills atrophy. “Continuous exposure to AI might reduce the ADR (adesoma detection rate) of standard non-AI assisted colonoscopy, suggesting a negative effect on endoscopist behaviour.” (science speak for saying that radiologists get worse at seeing tumors in scans once they’ve used AI): https://www.thelancet.com/journals/langas/article/PIIS2468-1253(25)00133-5/abstract
Nobody who cares about the future should be using this stuff for anything.
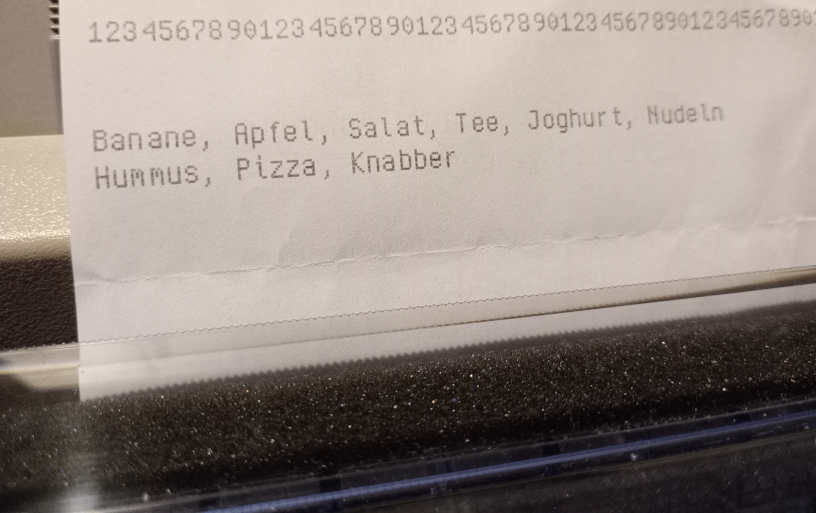
Android shopping list apps disappointed me too many times, so I went back to writing these lists by hand a while ago.
Here’s what’s more fun: Write them in Vim and then print them on the dotmatrix printer. 🥳
And, because I can, I use my own font for that, i.e. ImageMagick renders an image file and then a little tool converts that to ESC/P so I can dump it to /dev/usb/lp0.
(I have so much scrap paper from mail spam lying around that I don’t feel too bad about this. All these sheets would go straight to the bin otherwise.)