Portion of the modified Twitter TOS that goes into effect today (it’s on right now), as summarised (ironically) by Google’s Gemini:
“In simpler terms, this means that when you share your content (like text, images, or videos) on the service, you’re giving the company permission to use it in various ways. They can copy, modify, distribute, and even use it to train their AI models. This includes sharing your content with others and using it on other platforms. You won’t be paid for this, but using the service itself is considered enough compensation.”
@prologic@twtxt.net what do we make of Labor’s proposed social media minimum age ban, I.e ID verification, and the likes of Yarn? I haven’t been able to find out exactly how far the legislation goes, but some have said it’s broad enough to include any site that even has a comment section 🤔 but that could be FUD.
↳
In-reply-to
»
Thanks @lyse! I'm replying here https://text.eapl.mx/reply-to-lyse-about-twtxt
⤋ Read More
Thank you, @eapl.me@eapl.me! No need to apologize in the introduction, all good. :-)
Section 3: I’m a bit on the fence regarding documenting the HTTP caching headers. It’s a very general HTTP thing, so there is nothing special about them for twtxt. No need for the Twtxt Specification to actually redo it. But on the other hand, a short hint could certainly help client developers and feed authors. Maybe it’s thanks to my distro’s Ngninx maintainer, but I did not configure anything for the Last-Modified and ETag headers to be included in the response, the web server just already did it automatically.
The more that I think about it while typing this reply, the more I think your recommendation suggestion is actually really great. It will definitely beneficial for client developers. In almost all client implementation cases I’d say one has to actually do something specifically in the code to send the If-Modified-Since and/or If-None-Match request headers. There is no magic that will do it automatically, as one has to combine data from the last response with the new request.
But I also came across feeds that serve zero response headers that make caching possible at all. So, an explicit recommendation enables feed authors to check their server setups. Yeah, let’s absolutely do this! :-)
Regarding section 4 about feed discovery: Yeah, non-HTTP transport protocols are an issue as they do not have User-Agent headers. How exactly do you envision the discovery_url to work, though? I wouldn’t limit the transports to HTTP(S) in the Twtxt Specification, though. It’s up to the client to decide which protocols it wants to support.
Since I currently rely on buckket’s twtxt client to fetch the feeds, I can only follow http(s):// (and file://) feeds. But in tt2 I will certainly add some gopher:// and gemini:// at some point in time.
Some time ago, @movq@www.uninformativ.de found out that some Gopher/Gemini users prefer to just get an e-mail from people following them: https://twtxt.net/twt/dikni6q So, it might not even be something to be solved as there is no problem in the first place.
Section 5 on protocol support: You’re right, announcing the different transports in the url metadata would certainly help. :-)
Section 7 on emojis: Your idea of TUI/CLI avatars is really intriguing I have to say. Maybe I will pick this up in tt2 some day. :-)
↳
In-reply-to
»
FYI 👋 I will be deleting the following inactive users from my pod (twtxt.net) soon™:
⤋ Read More
@prologic@twtxt.net Yeah, the principle of data economy. :-)
Btw. if you blindly run the command again in a few days, your query might match new feeds that are not included in today’s list. Hence, some accounts might be dropped without a warning. But then, they probably don’t care.
Lawsuit Accuses PowerSchool of Selling Student Data To 3rd Parties
A former teacher has filed a federal lawsuit against PowerSchool, alleging the education technology giant illegally sells student data to third parties without proper consent. Emily Cherkin, lead plaintiff in the class action suit filed in San Francisco, claims PowerSchool has amassed 345 terabytes of data from 440 school districts, including … ⌘ Read more
↳
In-reply-to
»
Three days from today, towards the end of the day, we in the US will have an idea of who the nation's presiding person will be for the next four years. In the 32 years I have lived here, I have never been more worried about an election outcome.
⤋ Read More
@xuu@txt.sour.is done, and done, and done. The three of us dropped our mail-in ballots, and received confirmation they are counted. Living in a red state (well, kid said it is more like purple now) makes me sad, and mad, but I have done what I can—and that includes explaining things to others, and encouraging them to vote.
↳
In-reply-to
»
@prologic I'm not a yarnd user, so it doesn't matter a whole lot to me, but FWIW I'm not especially keen on changing how I format my twts to work around yarnd's quirks.
⤋ Read More
@bender@twtxt.net @prologic@twtxt.net I’m not exactly asking yarnd to change. If you are okay with the way it displayed my twts, then by all means, leave it as is. I hope you won’t mind if I continue to write things like 1/4 to mean “first out of four”.
What has text/markdown got to do with this? I don’t think Markdown says anything about replacing 1/4 with ¼, or other similar transformations. It’s not needed, because ¼ is already a unicode character that can simply be directly inserted into the text file.
What’s wrong with my original suggestion of doing the transformation before the text hits the twtxt.txt file? @prologic@twtxt.net, I think it would achieve what you are trying to achieve with this content-type thing: if someone writes 1/4 on a yarnd instance or any other client that wants to do this, it would get transformed, and other clients simply wouldn’t do the transformation. Every client that supports displaying unicode characters, including Jenny, would then display ¼ as ¼.
Alternatively, if you prefer yarnd to pretty-print all twts nicely, even ones from simpler clients, that’s fine too and you don’t need to change anything. My 1/4 -> ¼ thing is nothing more than a minor irritation which probably isn’t worth overthinking.
↳
In-reply-to
»
@aelaraji And pray tell/share with us what these magical commands do? 🤣
⤋ Read More
@prologic@twtxt.net Sure!! gg=G auto-indents your documents, as for the rest it’s:
vfor selection mode,cfor change anddfor delete actions as usual.
- followed by either ‘a
for around ori` for inside/in-between whatever special character comes after it
_ the [, (, “ … special characters define the perimeter/extent of the action.
i.e: ci" would be change the text under the cursor between quotes and da[ _delete text and brackets included_
I’ve linked a reference in the first twt, hope you find it useful.
Had a great time at the Duisburg zoo yesterday including the amazing dolphin show
↳
In-reply-to
»
Gemini/Gopher Twtxt feeds account for less than 1% in existence:
⤋ Read More
@prologic@twtxt.net does that include mine? otherwise it would make them 8 and 5, maybe even throw off your maths by 0.00001% 😆 … and, come on! 1.04% seems like a good ratio considering how many gopher holes and gem capsules compared to how many Web servers out there in the world 😂
Sharing the comments of the poll (anonymous so I have no idea whom the comments are from):
your poll should include questions about markdown. personally i think inline bits like style, links, images are yes. block quotes, code blocks, bullet lists are mid. but tables and footnotes are no.
Yes sorry about this, I wasn’t able to change much after publishing the poll 😅
#fzf is the new emacs: a tool with a simple purpose that has evolved to include an #email client. https://sr.ht/~rakoo/omail/
I’m being a little silly, of course. fzf doesn’t actually check your email, but it appears to be basically the whole user interface for that mail program, with #mblaze wrangling the emails.
I’ve been thinking about how I handle my email, and am tempted to make something similar. (When I originally saw this linked the author was presenting it as an example tweaked to their own needs, encouraging people to make their own.)
This approach could surely also be combined with #jenny, taking the place of (neo)mutt. For example mblaze’s mthread tool presents a threaded discussion with indentation.
↳
In-reply-to
»
@prologic Thanks for writing that up!
⤋ Read More
@falsifian@www.falsifian.org I believe the preserve means to include the original subject hash in the start of the twt such as (#somehash)
↳
In-reply-to
»
Okay folks, I've spent all day on this today, and I think its in "good enough"™ shape to share:
⤋ Read More
@prologic@twtxt.net Thanks for writing that up!
I hope it can remain a living document (or sequence of draft revisions) for a good long time while we figure out how this stuff works in practice.
I am not sure how I feel about all this being done at once, vs. letting conventions arise.
For example, even today I could reply to twt abc1234 with “(#abc1234) Edit: …” and I think all you humans would understand it as an edit to (#abc1234). Maybe eventually it would become a common enough convention that clients would start to support it explicitly.
Similarly we could just start using 11-digit hashes. We should iron out whether it’s sha256 or whatever but there’s no need get all the other stuff right at the same time.
I have similar thoughts about how some users could try out location-based replies in a backward-compatible way (append the replyto: stuff after the legacy (#hash) style).
However I recognize that I’m not the one implementing this stuff, and it’s less work to just have everything determined up front.
Misc comments (I haven’t read the whole thing):
Did you mean to make hashes hexadecimal? You lose 11 bits that way compared to base32. I’d suggest gaining 11 bits with base64 instead.
“Clients MUST preserve the original hash” — do you mean they MUST preserve the original twt?
Thanks for phrasing the bit about deletions so neutrally.
I don’t like the MUST in “Clients MUST follow the chain of reply-to references…”. If someone writes a client as a 40-line shell script that requires the user to piece together the threading themselves, IMO we shouldn’t declare the client non-conforming just because they didn’t get to all the bells and whistles.
Similarly I don’t like the MUST for user agents. For one thing, you might want to fetch a feed without revealing your identty. Also, it raises the bar for a minimal implementation (I’m again thinking again of the 40-line shell script).
For “who follows” lists: why must the long, random tokens be only valid for a limited time? Do you have a scenario in mind where they could leak?
Why can’t feeds be served over HTTP/1.0? Again, thinking about simple software. I recently tried implementing HTTP/1.1 and it wasn’t too bad, but 1.0 would have been slightly simpler.
Why get into the nitty-gritty about caching headers? This seems like generic advice for HTTP servers and clients.
I’m a little sad about other protocols being not recommended.
I don’t know how I feel about including markdown. I don’t mind too much that yarn users emit twts full of markdown, but I’m more of a plain text kind of person. Also it adds to the length. I wonder if putting a separate document would make more sense; that would also help with the length.
↳
In-reply-to
»
@prologic I wouldn't want my client to honour delete requests. I like my computer's memory to be better than mine, not worse, so it would bug me if I remember seeing something and my computer can't find it.
⤋ Read More
@prologic@twtxt.net Do you have a link to some past discussion?
Would the GDPR would apply to a one-person client like jenny? I seriously hope not. If someone asks me to delete an email they sent me, I don’t think I have to honour that request, no matter how European they are.
I am really bothered by the idea that someone could force me to delete my private, personal record of my interactions with them. Would I have to delete my journal entries about them too if they asked?
Maybe a public-facing client like yarnd needs to consider this, but that also bothers me. I was actually thinking about making an Internet Archive style twtxt archiver, letting you explore past twts, including long-dead feeds, see edit histories, deleted twts, etc.
I wrote some code to try out non-hash reply subjects formatted as (replyto ), while keeping the ability to use the existing hash style.
I don’t think we need to decide all at once. If clients add support for a new method then people can use it if they like. The downside of course is that this costs developer time, so I decided to invest a few hours of my own time into a proof of concept.
With apologies to @movq@www.uninformativ.de for corrupting jenny’s beautiful code. I don’t write this expecting you to incorporate the patch, because it does complicate things and might not be a direction you want to go in. But if you like any part of this approach feel free to use bits of it; I release the patch under jenny’s current LICENCE.
Supporting both kinds of reply in jenny was complicated because each email can only have one Message-Id, and because it’s possible the target twt will not be seen until after the twt referencing it. The following patch uses an sqlite database to keep track of known (url, timestamp) pairs, as well as a separate table of (url, timestamp) pairs that haven’t been seen yet but are wanted. When one of those “wanted” twts is finally seen, the mail file gets rewritten to include the appropriate In-Reply-To header.
Patch based on jenny commit 73a5ea81.
https://www.falsifian.org/a/oDtr/patch0.txt
Not implemented:
- Composing twts using the (replyto …) format.
- Probably other important things I’m forgetting.
Regarding jenny development: There have been enough changes in the last few weeks, imo. I want to let things settle for a while (potential bugfixes aside) and then I’m going to cut a new release.
And I guess the release after that is going to include all the threading/hashing stuff – if we can decide on one of the proposals. 😂
@sorenpeter@darch.dk I like this idea. Just for fun, I’m using a variant in this twt. (Also because I’m curious how it non-hash subjects appear in jenny and yarn.)
URLs can contain commas so I suggest a different character to separate the url from the date. Is this twt I’ve used space (also after “replyto”, for symmetry).
I think this solves:
- Changing feed identities: although @mckinley@twtxt.net points out URLs can change, I think this syntax should be okay as long as the feed at that URL can be fetched, and as long as the current canonical URL for the feed lists this one as an alternate.
- editing, if you don’t care about message integrity
- finding the root of a thread, if you’re not following the author
An optional hash could be added if message integrity is desired. (E.g. if you don’t trust the feed author not to make a misleading edit.) Other recent suggestions about how to deal with edits and hashes might be applicable then.
People publishing multiple twts per second should include sub-second precision in their timestamps. As you suggested, the timestamp could just be copied verbatim.
↳
In-reply-to
»
Now WTF!? Suddenly, @falsifian's feed renders broken in my tt Python implementation. Exactly what I had with my Go rewrite. I haven't touched the Python stuff in ages, though. Also, tt and tt2 do not share any data at all.
⤋ Read More
@lyse@lyse.isobeef.org Sorry, I don’t think I ever had charset=utf8. I just noticed that a few days ago. OpenBSD’s httpd might not support including a parameter with the mime type, unfortunately. I’m going to look into it.
@prologic@twtxt.net, your first twtxt ever was o6dsrga, but I can’t find the source for it (the raw file). I reset everything, and re-fetched fresh feeds (allegedly including archives). Where is it?
the first version of the minibase flake cdn is online as of today. more details on how this is populated and funded will be coming along soon. currently minibase includes a very small selection of packages, but you can install them using the experimental flakes feature today! https://src.cyb.red/
↳
In-reply-to
»
The original twt is unavailable. It may have been edited or deleted, or is from an unknown or muted feed.
⤋ Read More
@prx@si3t.ch I haven’t messed with rdomains, but still it might help if you included the command that produced that error (and whether you ran it as root).
↳
In-reply-to
»
On the Subject of Feed Identities; I propose the following:
⤋ Read More
So this is a great thread. I have been thinking about this too.. and what if we are coming at it from the wrong direction? Identity being tied to a given URL has always been a pain point. If i get a new URL its almost as if i have a new identity because not only am I serving at a new location but all my previous communications are broken because the hashes are all wrong.
What if instead we used this idea of signatures to thread the URLs together into one identity? We keep the URL to Hash in place. Changing that now is basically a no go. But we can create a signature chain that can link identities together. So if i move to a new URL i update the chain hosted by my primary identity to include the new URL. If i have an archived feed that the old URL is now dead, we can point to where it is now hosted and use the current convention of hashing based on the first url:
The signature chain can also be used to rotate to new keys over time. Just sign in a new key or revoke an old one. The prior signatures remain valid within the scope of time the signatures were made and the keys were active.
The signature file can be hosted anywhere as long as it can be fetched by a reasonable protocol. So say we could use a webfinger that directs to the signature file? you have an identity like frank@beans.co that will discover a feed at some URL and a signature chain at another URL. Maybe even include the most recent signing key?
From there the client can auto discover old feeds to link them together into one complete timeline. And the signatures can validate that its all correct.
I like the idea of maybe putting the chain in the feed preamble and keeping the single self contained file.. but wonder if that would cause lots of clutter? The signature chain would be something like a log with what is changing (new key, revoke, add url) and a signature of the change + the previous signature.
# chain: ADDKEY kex14zwrx68cfkg28kjdstvcw4pslazwtgyeueqlg6z7y3f85h29crjsgfmu0w
# sig: BEGIN SALTPACK SIGNED MESSAGE. ...
# chain: ADDURL https://txt.sour.is/user/xuu
# sig: BEGIN SALTPACK SIGNED MESSAGE. ...
# chain: REVKEY kex14zwrx68cfkg28kjdstvcw4pslazwtgyeueqlg6z7y3f85h29crjsgfmu0w
# sig: ...
↳
In-reply-to
»
@aelaraji Venus?
⤋ Read More
@movq@www.uninformativ.de Yep, that’s very nice music. :-)
Can’t help myself, but I have to include the Uranus song now. :-D https://www.youtube.com/watch?v=OSWszdSHkyE#t=7
imo the only useful application would be so that I never have to get a new computer again unless mine breaks. i like being able to talk to people from around the world, so its going to have to include internet and video (y’all saw the impact tiktok had on the gaza situation, can’t deny that video is important)
↳
In-reply-to
»
There is a bug in
⤋ Read More
yarnd that's been around for awhile and is still present in the current version I'm running that lets a person hit a constructed URL like
@prologic@twtxt.net I believe you are not seeing the problem I am describing.
Hit this URL in your web browser:
https://twtxt.net/external?nick=lovetocode999&uri=https://socialmphl.com/story19510368/doujin
That’s your pod. I assume you don’t have a user named lovetocode999 on your pod. Yet that URL returns HTTP status 200, and generates HTML, complete with a link to https://socialmphl.com/story19510368/doujin, which is not a twtxt feed (that’s where the twtxt.txt link goes if you click it). That link could be to anything, including porn, criminal stuff, etc, and it will appear to be coming from your twtxt.net domain.
What I am saying is that this is a bug. If there is no user lovetocode999 on the pod, hitting this URL should not return HTTP 200 status, and it should definitely not be generating valid HTML with links in it.
Edit: Oops, I misunderstood the purpose of this /external endpoint. Still, since the uri is not a yarn pod, let alone one with a user named lovetocode999 on it, I stand by the belief that URLs like this should be be generating valid HTML with links to unknown sites. Shouldn’t it be possible to construct a valid target URL from the nick and uri instead of using the pod’s /external endpoint?
Hello twtxt! I’m James (or @falsifian@www.falsifian.org). I live in Toronto. Recent interests include space complexity, simple software, and science fiction.
↳
In-reply-to
»
Congratulations to the British for getting rid of the Tories tyranny, and electing the forward thinking Labour party! 🥳
⤋ Read More
it works fine if you properly escape your urls!
 URIs include components and subcomponents that are delimited by
   characters in the "reserved" set.  These characters are called
   "reserved" because they may (or may not) be defined as delimiters by
   the generic syntax, by each scheme-specific syntax, or by the
   implementation-specific syntax of a URI's dereferencing algorithm.
   If data for a URI component would conflict with a reserved
   character's purpose as a delimiter, then the conflicting data must be
   percent-encoded before the URI is formed.

      reserved    = gen-delims / sub-delims
      gen-delims  = ":" / "/" / "?" / "#" / "[" / "]" / "@"
      sub-delims  = "!" / "$" / "&" / "'" / "(" / ")"
                  / "*" / "+" / "," / ";" / "="
Pinellas County - Warm up: 2.41 miles, 00:09:08 average pace, 00:21:59 duration
included some strides and felt pretty strong
#running
↳
In-reply-to
»
If you're reading this, it is now possible to post on twtxt.net using Ladybird!
⤋ Read More
There is JavaScript, but not everything is implemented (properly). They’re writing everything including the JavaScript engine from scratch.
A huge effort 😲
↳
In-reply-to
»
Yeah sorry just realised, but just checked again and the referrer is the same (
⤋ Read More
/post) on either the POST or the GET 🤔
@prologic@twtxt.net Sorry, my messages don’t get included in the current convo unless I tag you. Guess something gets lossed in translation with this weird posting issue. ANYWAY, it is rather perplexing. Clearly only an issue on my Pod, but what could the source of it be 🤔
@prologic@twtxt.net Righteo, so rookie error - I obviously had some untracked, rather important files for starting my pod and I ran a make clean. Why I originally had them in the git directory is anyone’s guess. Anyway it blew away those files including the database so that’s that. So your good self and @bender@twtxt.net etc - apologies but your profiles got nuked as well (as did my own but easily recreated).
Another thing I noticed which was the reason I ran make clean in the first place. I noticed my pod was being built with Go 1.22.4. Could this be a problem @prologic? preflight.sh actually errors out about it…
↳
In-reply-to
»
@bender To quote from the german version of ISO 27001:
⤋ Read More
@bender@twtxt.net well there is “supercalifragilisticexpialidocious”!
I usualy hear people ask Harry Mack (a freestyle rapper) to include it in his freestyles. 😆
↳
In-reply-to
»
⤋ Read More
@hecanjog@hecanjog.com You need to include the full URL for the audio file for this to work across servers/pods ;)
Hey @sorenpeter@darch.dk, I’m sorry to tell you, but the prev field in your feed’s headers is invalid. 😅
First, it doesn’t include the hash of the last twt in the archive. Second, and that’s probably more important, it forms an infinite loop: The prev field of your main feed specifies http://darch.dk/twtxt-archive.txt and that file then again specifies http://darch.dk/twtxt-archive.txt. Some clients might choke on this, mine for example. 😂 I’ll push a fix soon, though.
For reference, the prev field is described here: https://dev.twtxt.net/doc/archivefeedsextension.html
↳
In-reply-to
»
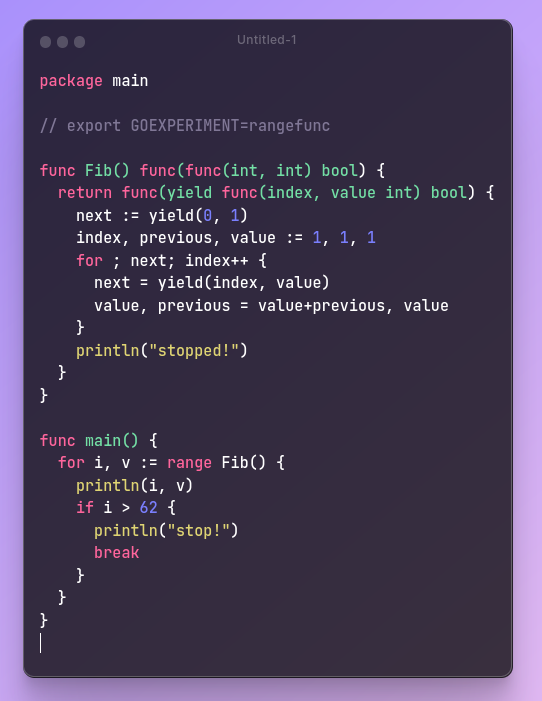
Go 1.22.0 introduces a new experiment for range functions. Have you tried them out? What do you think it can make easier to accomplish?
⤋ Read More
the function can yield two values to include an index.
Google Chrome Gains AI Features Including a Writing Helper
Google is adding new AI features to Chrome, including tools to organize browser tabs, customize themes, and assist users with writing online content such as reviews and forum posts.
The writing helper is similar to an AI-powered feature already offered in Google’s experimental search experience, SGE, which helps users draft emails in various tones and lengths. W … ⌘ Read more
↳
In-reply-to
»
@xuu That was one of the horror puzzles where I had to look for help. 🥴 I modelled my solution after this: https://www.youtube.com/watch?v=2pDSooPLLkI (I can’t explain it better than the video anyway.) It takes a second on my machine and that’s with my own hashmap implementation which is probably not the fastest one.
⤋ Read More
OH MY FREAKING HECK. So.. I made my pather able to run as Dijkstra or A* if the interface includes a heuristic.. when i tried without the heuristic it finished faster :|
So now to figure out why its not working right.
↳
In-reply-to
»
@xuu That was one of the horror puzzles where I had to look for help. 🥴 I modelled my solution after this: https://www.youtube.com/watch?v=2pDSooPLLkI (I can’t explain it better than the video anyway.) It takes a second on my machine and that’s with my own hashmap implementation which is probably not the fastest one.
⤋ Read More
i am wondering if maybe i need a better heap like a btree backed one instead of just list sort on Dequeue.
I found a bug where i didnt include an open/closed list that seemed to shave off a little. right now it runs in about 70 seconds on my machine.. it takes over the 300s limit when it runs on the testrunner on the same box.. docker must be restricting resources for it.
I might come back to it after i work through improving my code for day 23. Its similar but looking for the longest path instead of shortest.
I’m really bad at competitive programming. 🙄 For today’s #AdventOfCode puzzle, I spent an eternity trying to understand exactly what kind of bG9naWMgY2lyY3VpdAo= the puzzle input describes – I haven’t done that in well over a decade, so I made little progress. I knew right from the start that SSBoYWQgdG8gbG9vayBmb3IgY3ljbGUgbGVuZ3RocyBhbmQgdGhlbiBmaW5kIHRoZSBMQ00K. It just didn’t occur to me to just run my program on cGFydGlhbCBpbnB1dAo= and print those numbers. 🥴 I only did that after over 4 hours (including time to debug my nasty C code) and then, boom, solution …
- does this need to be said? - does this need to be said by me? - does this need to be said by me, now? When to Shut Up: A Visual Guide (With Included Algorithm) | Hacker News
↳
In-reply-to
»
@prologic I don't understand what you're saying.
⤋ Read More
podman works with TLS. It does not have the "--docker" siwtch so you have to remove that and use the exact replacement commands that were in that github comment.
@prologic@twtxt.net what do you mean when you say “Docker API”? There are multiple possible meanings for that. podman conforms to some of Docker’s APIs and it’s unclear to me which one you say it’s not conforming to.
You just have to Google “podman Docker API” and you find stuff like this: https://www.redhat.com/sysadmin/podman-rest-api
What is Podman’s REST API?Podman’s REST API consists of two components:
- A Docker-compatible portion called Compat API
- A native portion called Libpod API that provides access to additional features not available in Docker, including pods
Or this: https://docs.podman.io/en/latest/markdown/podman-system-service.1.html
The REST API provided by podman system service is split into two parts: a compatibility layer offering support for the Docker v1.40 API, and a Podman-native Libpod layer.
All it’s about definitions:
“people who want clarity things will tighten their definitions, so they’ll reduce the scope or boundaries. People who are attempting to misuse definitions will shift them around or weaken the definitions to include more stuff. They get less precise.”
https://theprogrammersparadox.blogspot.com/2022/12/definitions.html
↳
In-reply-to
»
ASCIIFlow This is kind of cool 😅
⤋ Read More
@prologic@twtxt.net I see what you mean about tldraw. I looked at their github repository and it seems like they are distributing it as an npm package for people who want to include a whiteboard in their Javascript-based frontend. I didn’t see a way to just launch the thing.
I have half a mind to write a little scala frontend that sets up one of these, since scalajs makes it very easy to use these Javascript web component things while making it look like you’re writing scala.
Question to all you Gophers out there: How do you deal with custom errors that include more information and different kinds of matching them?
I started with a simple var ErrPermissionNotAllowed = errors.New("permission not allowed"). In my function I then wrap that using fmt.Errorf("%w: %v", ErrPermissionNotAllowed, failedPermissions). I can match this error using errors.Is(err, ErrPermissionNotAllowed). So far so good.
Now for display purposes I’d also like to access the individual permissions that could not be assigned. Parsing the error message is obviously not an option. So I thought, I create a custom error type, e.g. type PermissionNotAllowedError []Permission and give it some func (e PermissionNotAllowedError) Error() string { return fmt.Sprintf("permission not allowed: %v", e) }. My function would then return this error instead: PermissionNotAllowedError{failedPermissions}
At some layers I don’t care about the exact permissions that failed, but at others I do, at least when accessing them. A custom func (e PermissionNotAllowedError) Is(target err) bool could match both the general ErrPermissionNotAllowed as well as the PermissionNotAllowedError. Same with As(…). For testing purposes the PermissionNotAllowedError would then also try to match the included permissions, so assertions in tests would work nicely. But having two different errors for different matching seems not very elegant at all.
Did you ever encounter this scenario before? How did you address this? Is my thinking flawed?
↳
In-reply-to
»
A GTK 4 application showing an empty window uses about 160 MB of RAM:
⤋ Read More
@movq@www.uninformativ.de
Doesn’t even compile on my system, which is apparently broken:
> cc -Wall -Wextra -o win win.c $(pkg-config --cflags --libs gtk4)
cc: error: unrecognized argument in option ‘-mfpmath=sse -msse -msse2 -pthread -I/usr/include/gtk-4.0 -I/usr/include/gio-unix-2.0 -I/usr/include/cairo -I/usr/include/pango-1.0 -I/usr/include/harfbuzz -I/usr/include/pango-1.0 -I/usr/include/fribidi -I/usr/include/harfbuzz -I/usr/include/gdk-pixbuf-2.0 -I/usr/include/x86_64-linux-gnu -I/usr/include/cairo -I/usr/include/pixman-1 -I/usr/include/uuid -I/usr/include/freetype2 -I/usr/include/libpng16 -I/usr/include/graphene-1.0 -I/usr/lib/x86_64-linux-gnu/graphene-1.0/include -I/usr/include/libmount -I/usr/include/blkid -I/usr/include/glib-2.0 -I/usr/lib/x86_64-linux-gnu/glib-2.0/include -lgtk-4 -lpangocairo-1.0 -lpango-1.0 -lharfbuzz -lgdk_pixbuf-2.0 -lcairo-gobject -lcairo -lgraphene-1.0 -lgio-2.0 -lgobject-2.0 -lglib-2.0’
cc: note: valid arguments to ‘-mfpmath=’ are: 387 387+sse 387,sse both sse sse+387 sse,387
Erlang Solutions: How ChatGPT improved my Elixir code. Some hacks are included.
I have been working as an Elixir developer for quite some time and recently came across the ChatGPT model. I want to share some of my experience interacting with it.
During my leisure hours, I am developing an open-source Elixir initiative, Crawly, that facilitates the extraction of structured data from the internet.
Here I want to demonstrate how … ⌘ Read more
TornadoVM Continues Adapting Java OpenJDK/GraalVM For Heterogeneous Hardware
A new release of TornadoVM is now available, the open-source plug-in to OpenJDK and GraalVM to allow for Java code to run on heterogeneous hardware with ease – including various GPU models as well as FPGAs… ⌘ Read more
Metaverse Could Contribute Up To 2.4% of US GDP By 2035, Study Shows
A study commissioned by Meta has found that the metaverse could contribute around 2.4% to U.S. annual GDP by 2035, equating to as much as $760 billion. Reuters reports: The concept of the metaverse includes augmented and virtual reality technologies that allow users to immerse themselves in a virtual world or overlay information digitally on … ⌘ Read more